 SimAgents
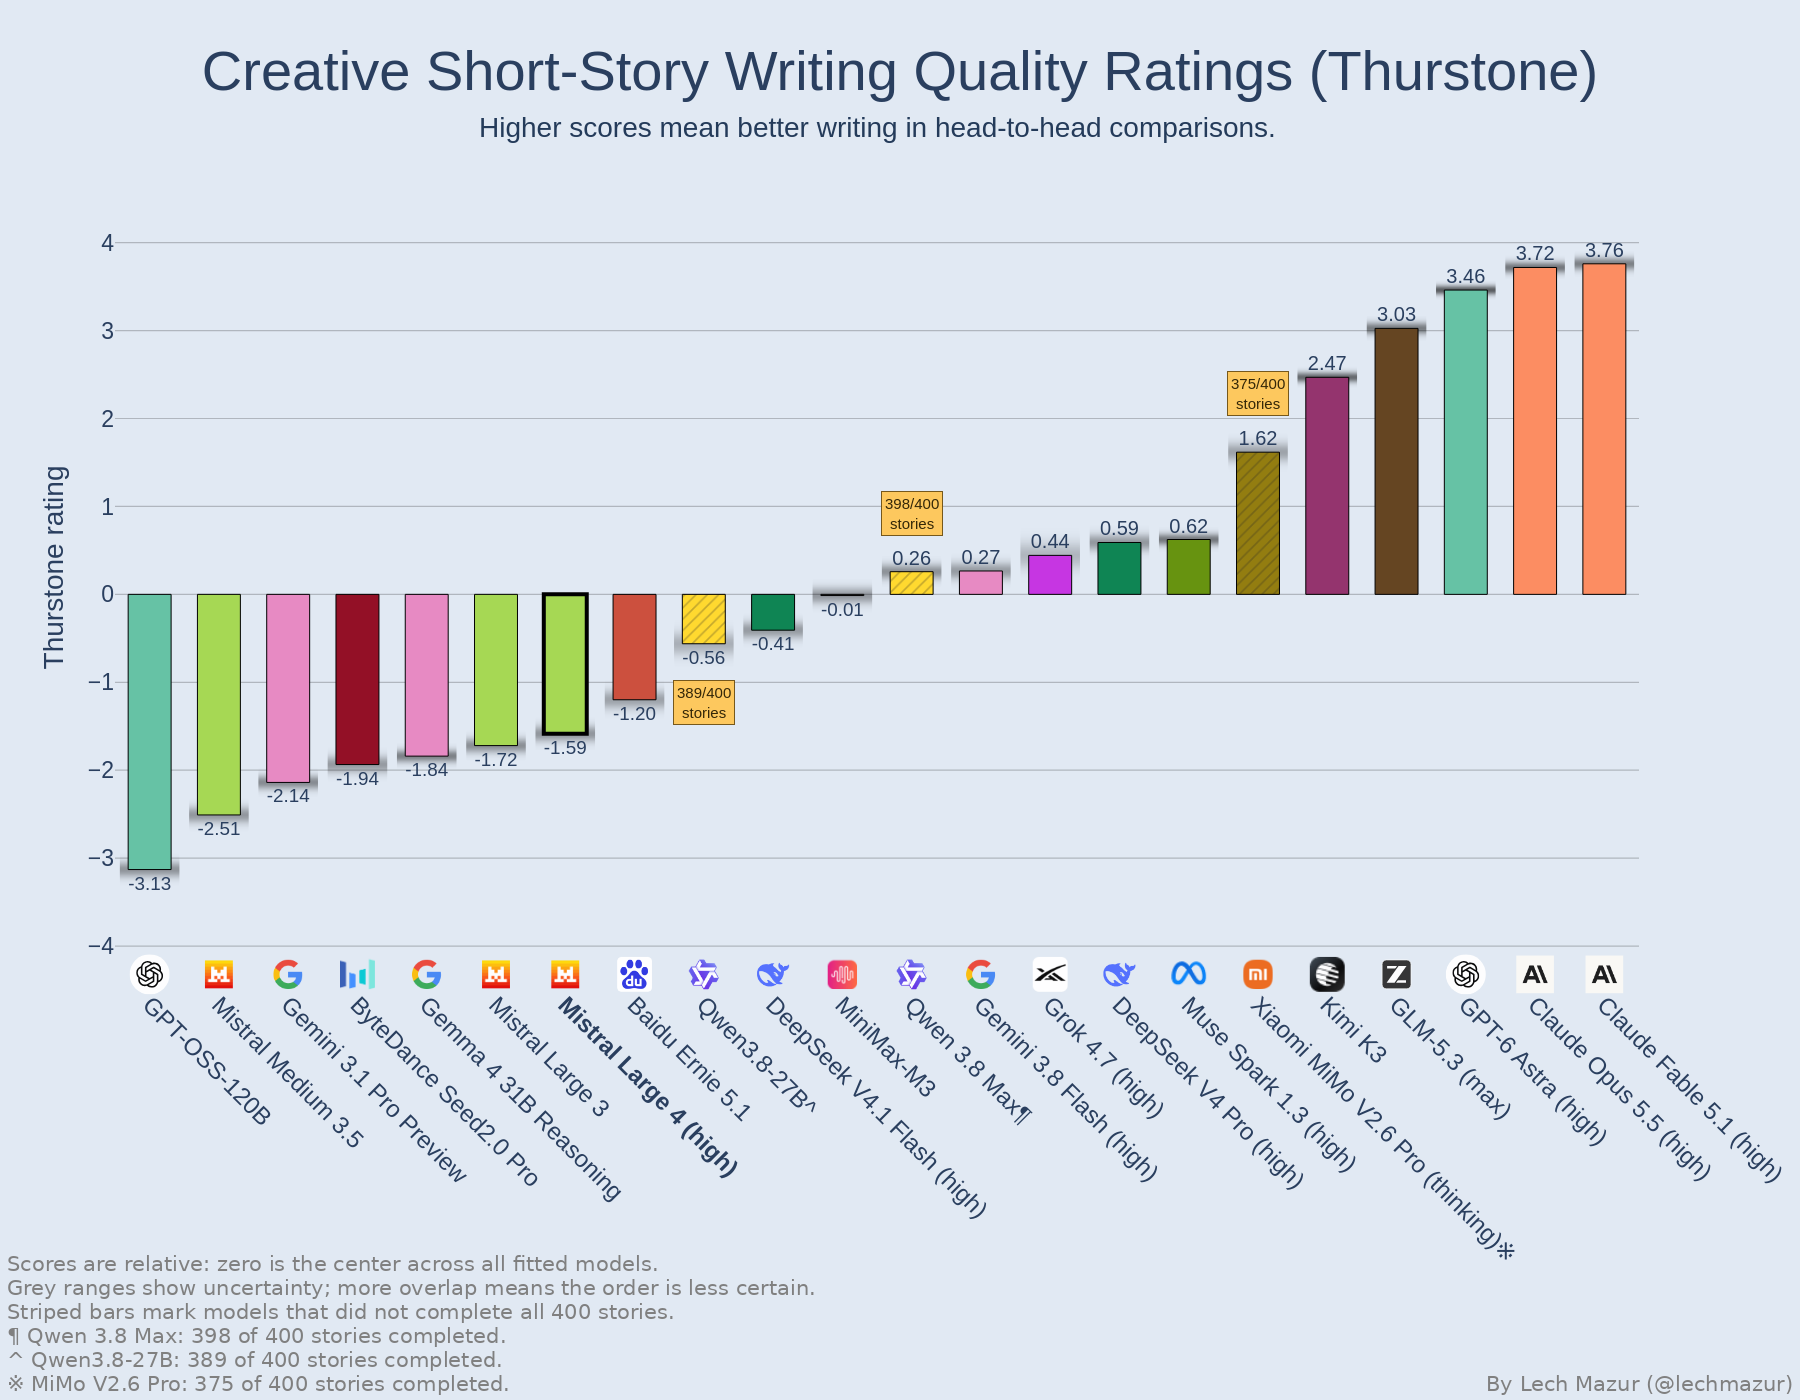
Findings and method.
Results as of 2026-10-07. Read the original publication ↗
Story coverage
- † Claude Opus 4.7: 347 of 400 stories completed.
- ‡ Claude Opus 4.8 high: 399 of 400 stories completed.
- § Claude Fable 5 high: 395 of 400 stories completed.
- ¶ Qwen 3.8 Max: 398 of 400 stories completed.
- ^ Qwen3.8-27B: 389 of 400 stories completed.
- ※ MiMo V2.6 Pro: 375 of 400 stories completed.
Striped bars and badges identify incomplete story sets. Quality comparisons concern completed stories. The latest evaluations returned 26,197/26,268 planned judgments; 71 unavailable judgments are excluded from the scores. The Opus 5.5 high versus Opus 5 high comparison covers 50 matched prompts, with 298/300 usable judgments.
Mistral Large 4 (high) completed all 400 prompts. Stories outside 600–800 words were regenerated from their original prompts, retaining the first response within range; 43 prompts required another draw, for 446 total generation calls. Its comparisons cover 26 opponents, including Mistral Large 3, with 20 matched stories per opponent and 3,112/3,120 usable judgments. Comparison coverage.
Head-to-head comparisons
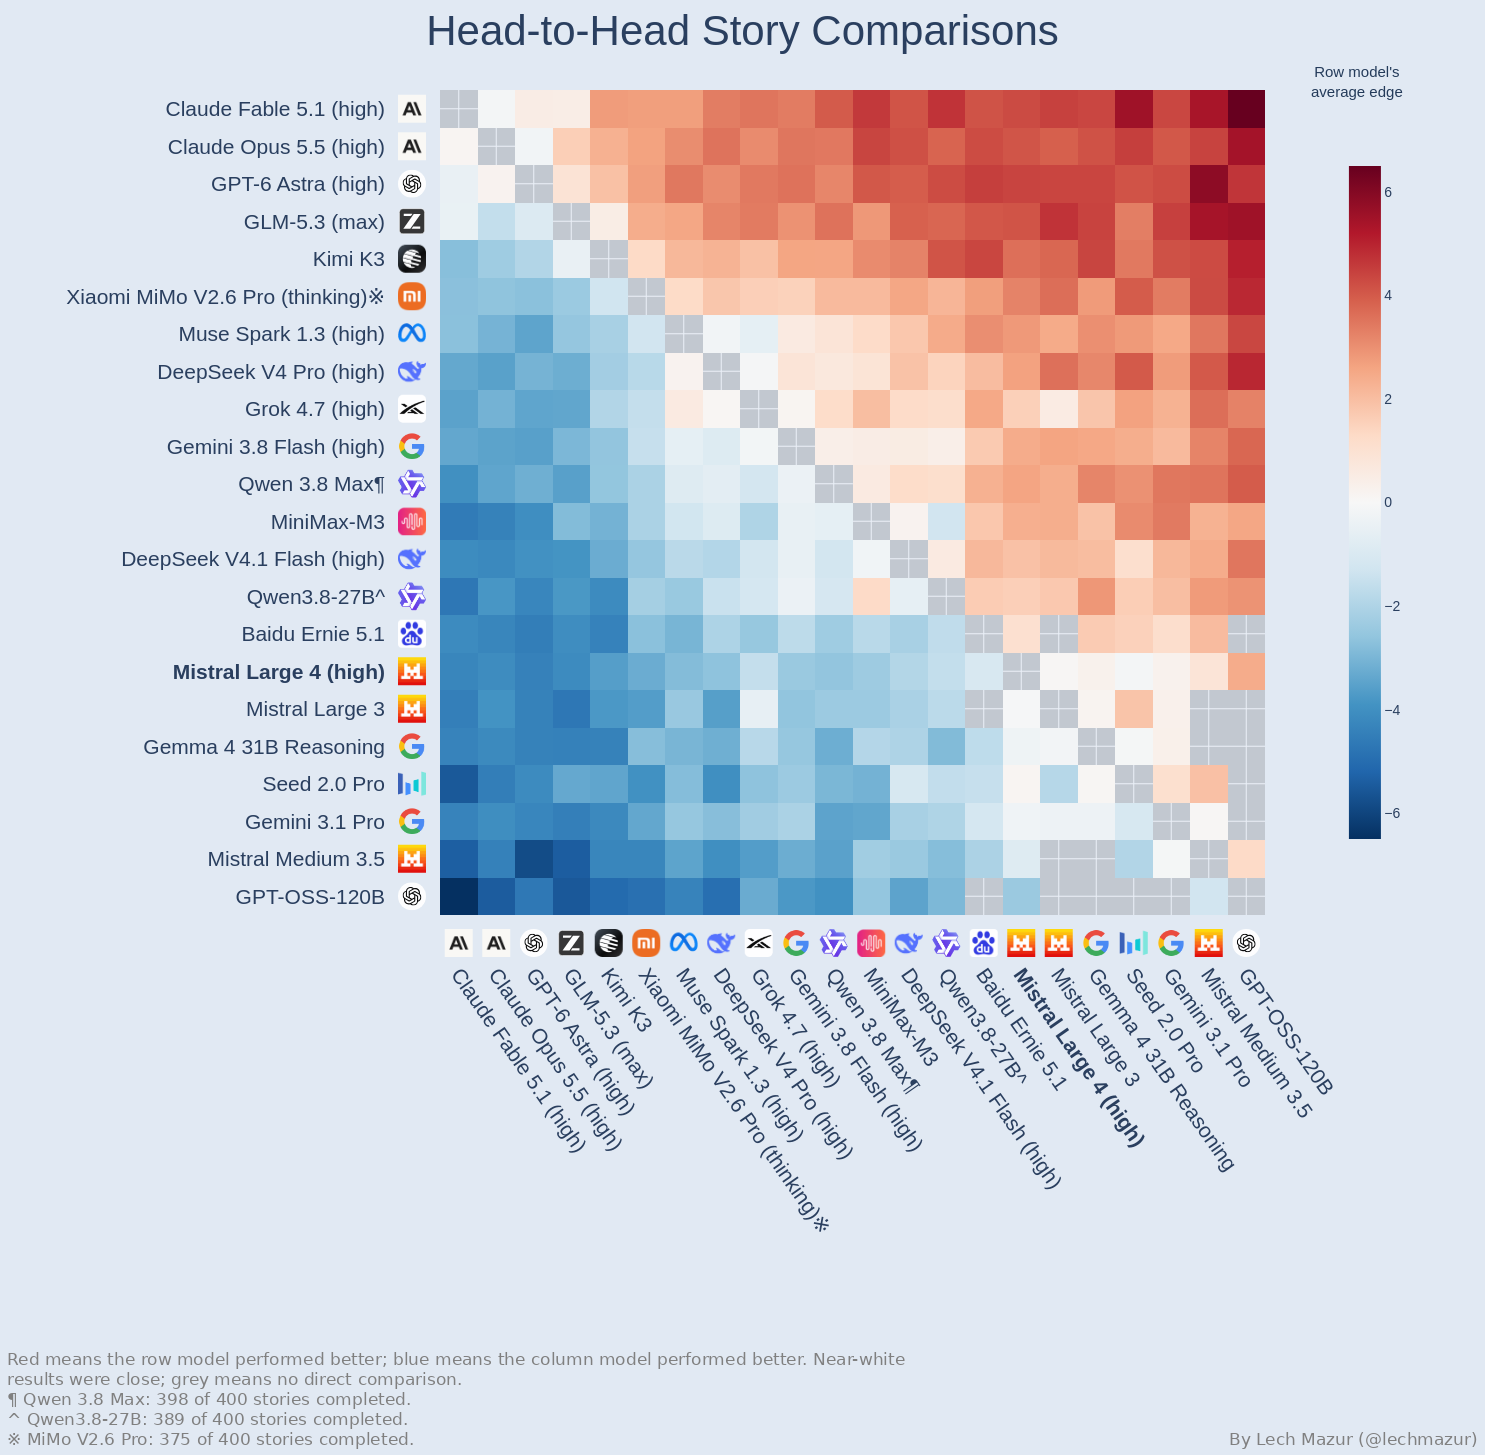
Read each cell by row. Red means the row model performed better, blue means the column model performed better, and grey means the models were not directly compared. Near-white cells indicate close results. Both axes follow the leaderboard order. Earlier and newer evaluations contribute to both this chart and the rankings.
Additional results
Evaluator Agreement
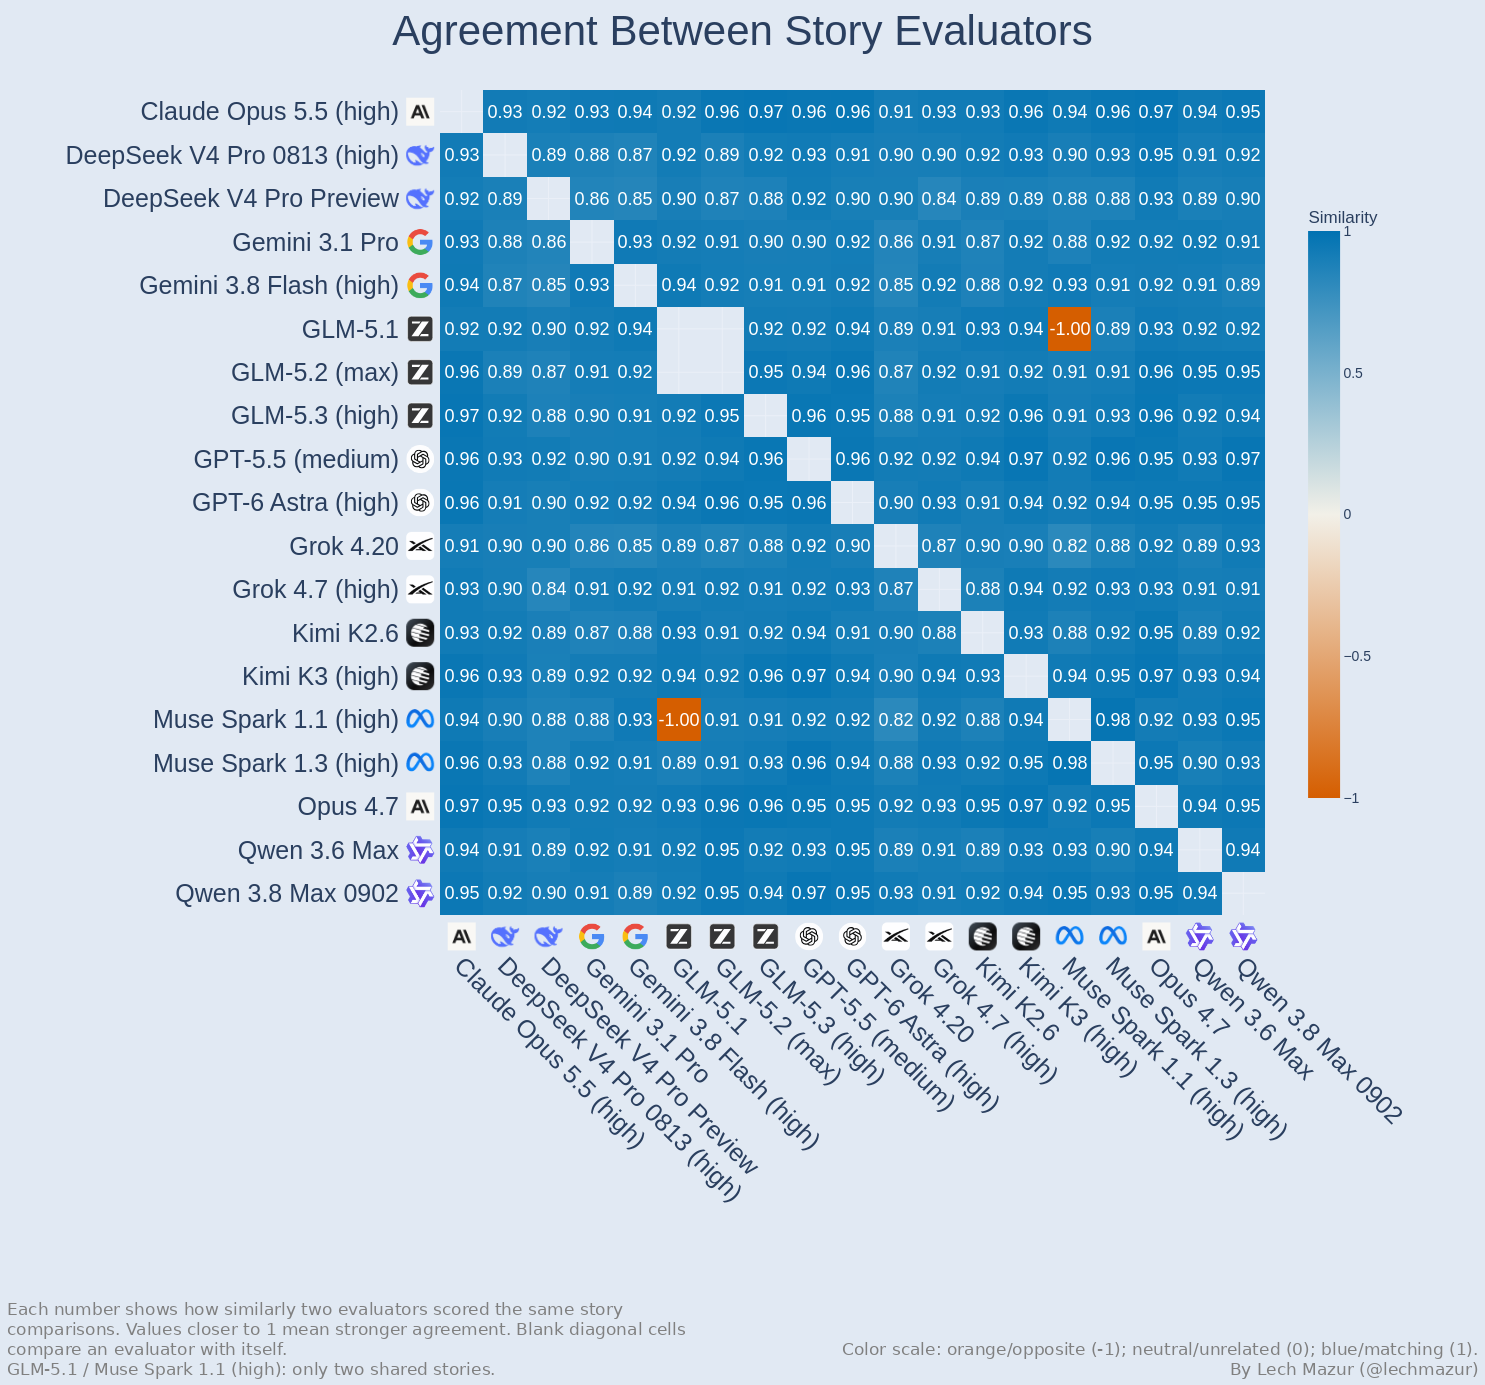
The matrix includes earlier and newer evaluator models. Each number shows how similarly two evaluators scored the story pairs they both read. Values closer to 1 indicate stronger agreement; 0 means no consistent relationship, and negative values mean opposing scoring patterns. Orange indicates negative correlations, and blue indicates positive correlations. Blank cells lack enough varied judgments to calculate a correlation; the diagonal is omitted. Agreement on these stories does not establish evaluator accuracy.
GLM-5.1 / Muse Spark 1.1 (high): only two shared stories. Shared-story counts accompany every evaluator pair.
Word Count Compliance
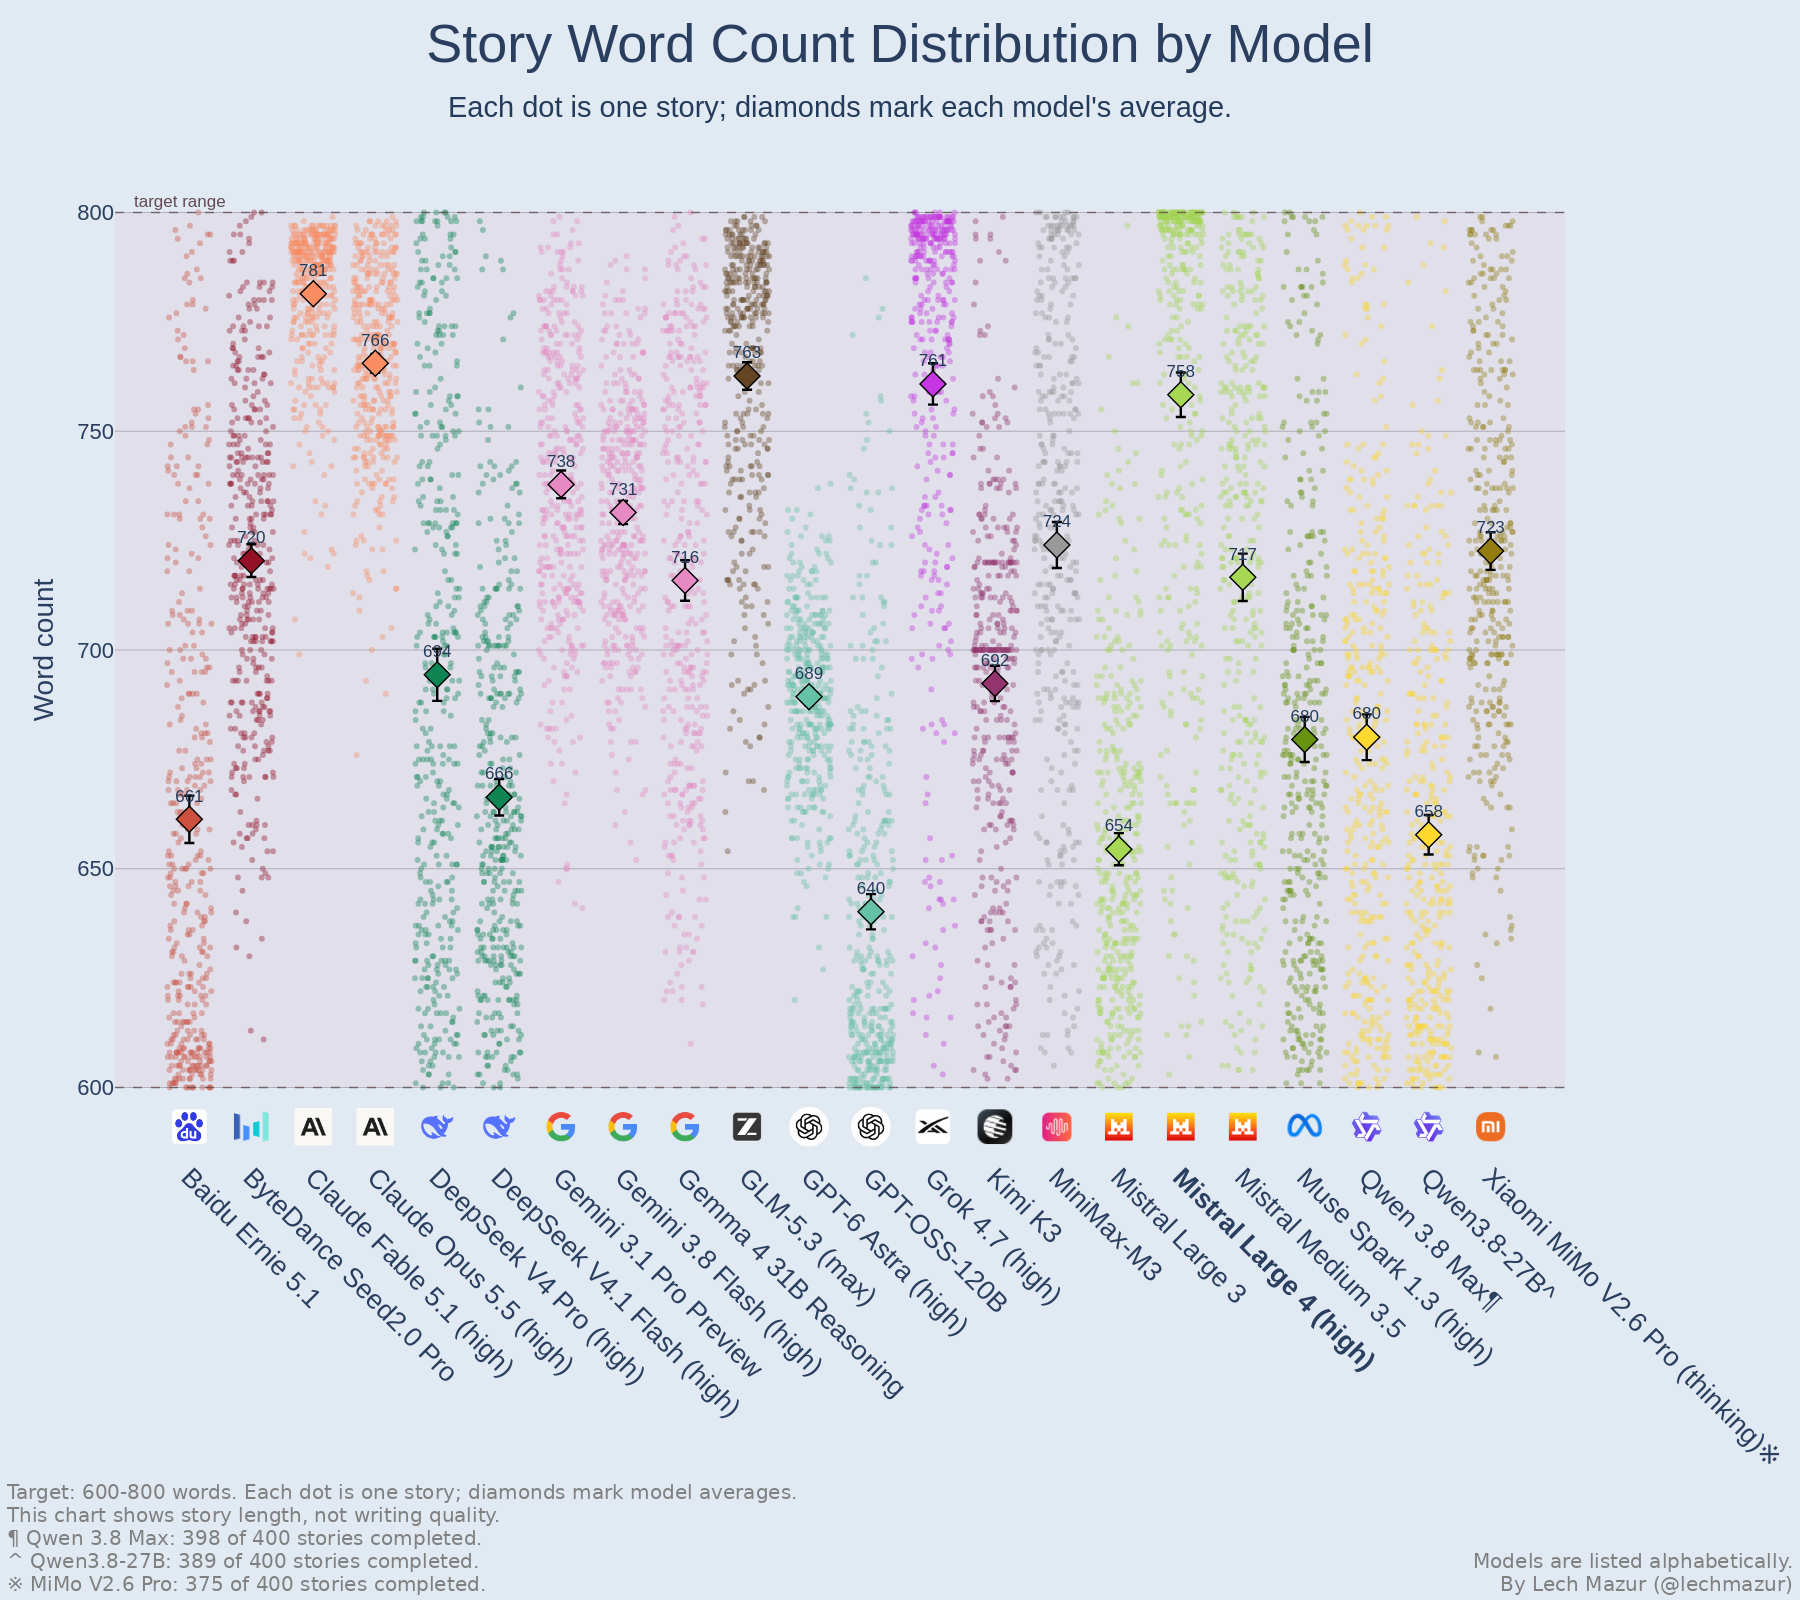
Each dot is one completed story; diamonds mark model averages. Thin vertical lines show uncertainty around the averages. The shaded band is the 600–800-word target. The chart includes 8,762 completed stories from all 22 displayed models. This measures length rather than writing quality.
Before Mistral was added, six stories that exceeded 800 words were regenerated using their original prompts; the first replacement within 600–800 words was retained. The 12 comparisons that used a replaced story were rerun with the same evaluators and both story orders. The rankings and charts use these replacements.
Combining Evaluations Over Time
Earlier and newer evaluators use the same instructions and scoring criteria. They have judged 1,200 of the same story pairs, covering all previously tested writer models. Different evaluator versions count separately, with one averaged judgment per evaluator on each story pair. Each story pair receives equal weight in the ranking. Ratings use a Thurstone statistical model with a correction for story presentation order.
The intervals reflect variation in completed comparisons. They do not account for how missing stories or judgments might change the scores, or how results would differ if only newer evaluators were used. Overlapping intervals mean small differences in rank may be uncertain.
What Is Measured
Every story must meaningfully incorporate ten required elements:
- character
- object
- concept
- attribute
- action
- method
- setting
- timeframe
- motivation
- tone
Candidate combinations are proposed for coherence and originality, then independently rated. The strongest combination for each seed becomes a fixed brief used by every writer model. A typical brief might combine a neutron-star researcher, butterfly-wing dust, gradual change, a storm-damaged greenhouse, "after the flood," and kindled humility.
Evaluators reward integration rather than keyword inclusion: the required object should affect the plot, the motivation should produce a consequential choice, and the tone should shape the story's development. Both stories in every comparison answer the same brief, holding prompt difficulty constant. Evaluators also consider prose, coherence, character, originality, and overall effectiveness. The public score combines their choices; it is not an average 0-10 grade.
Because the combinations are pre-screened for creative potential, the benchmark measures story construction under deliberately combinable constraints—not completely free-form writing or recovery from arbitrary incoherent prompts.
Method Summary
- Generate stories in the benchmark format.
- Build matched story-comparison prompts for models that wrote to the same required elements.
- Show each pair in both story orders to reduce first- or second-position effects.
- Repeat comparisons across evaluators and combine their choices.
- When evaluator models change, compare their judgments on shared stories before combining results.
- Calculate relative model scores and their uncertainty ranges.
Qualitative Pair Reports
Each report describes the models and stories compared. The Opus 5.5, Grok 4.7, and MiMo V2.6 Pro reports use newer evaluators; earlier reports use the evaluators available at the time.
New Models Compared with Their Predecessors collects twelve release-to-predecessor reports on a separate page.
New analyses give recurring writing habits, range and adaptability, and consistency separate treatment, with examples across different prompts. They examine repeated phrasing and story patterns as well as how flexibly each model changes its voice, tone, form, and narrative approach.
Data, stories, and prompts
Browse the story prompts and generated stories.
Current ratings and chart data include machine-readable leaderboard scores and uncertainty intervals, direct head-to-head results, matched story-pair results, and evaluator diagnostics.
Earlier benchmark data links to the immutable August 23, 2026 data release. That archive contains the exact evaluator commentary for both story orders, excluded or superseded responses, and the accompanying source story and prompt texts.