 SimAgents
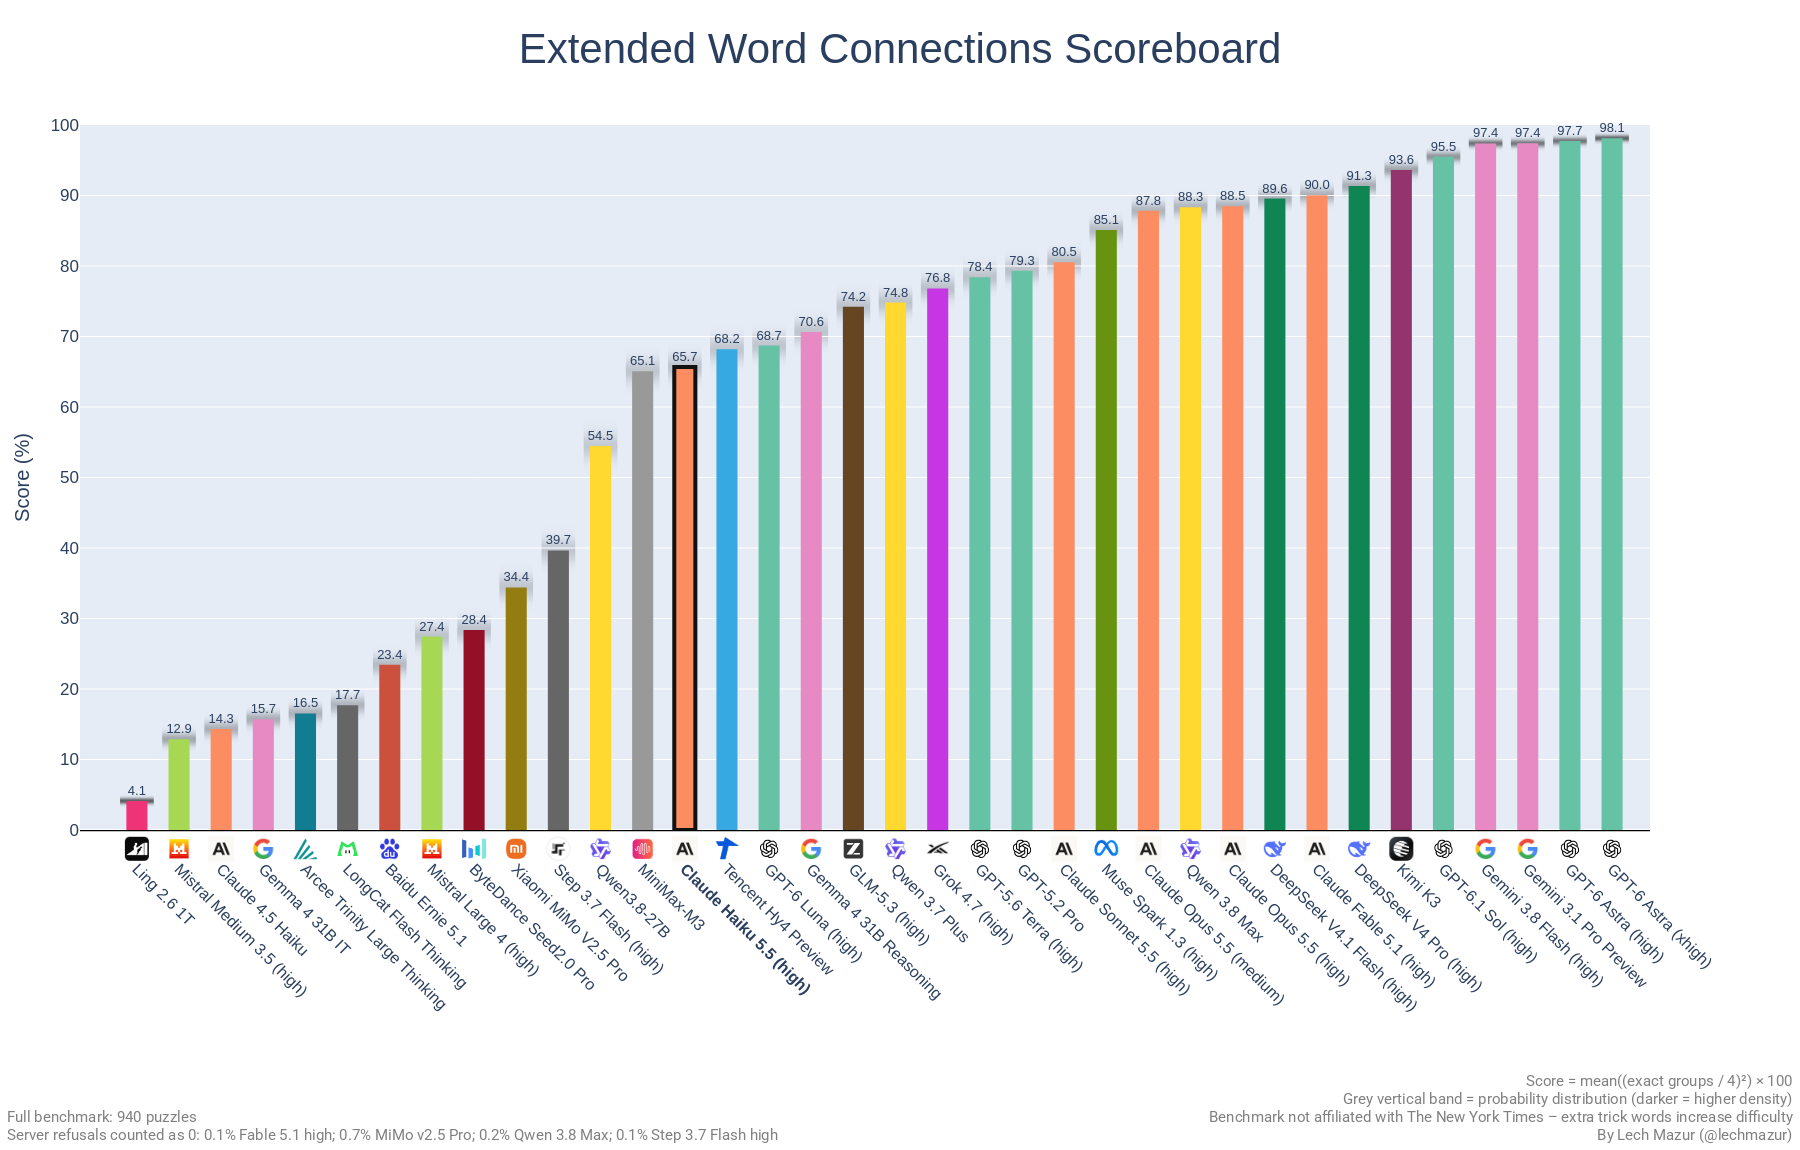
Findings and method.
Results as of 2026-10-08. Read the original publication ↗
Model comparisons
Model family progress
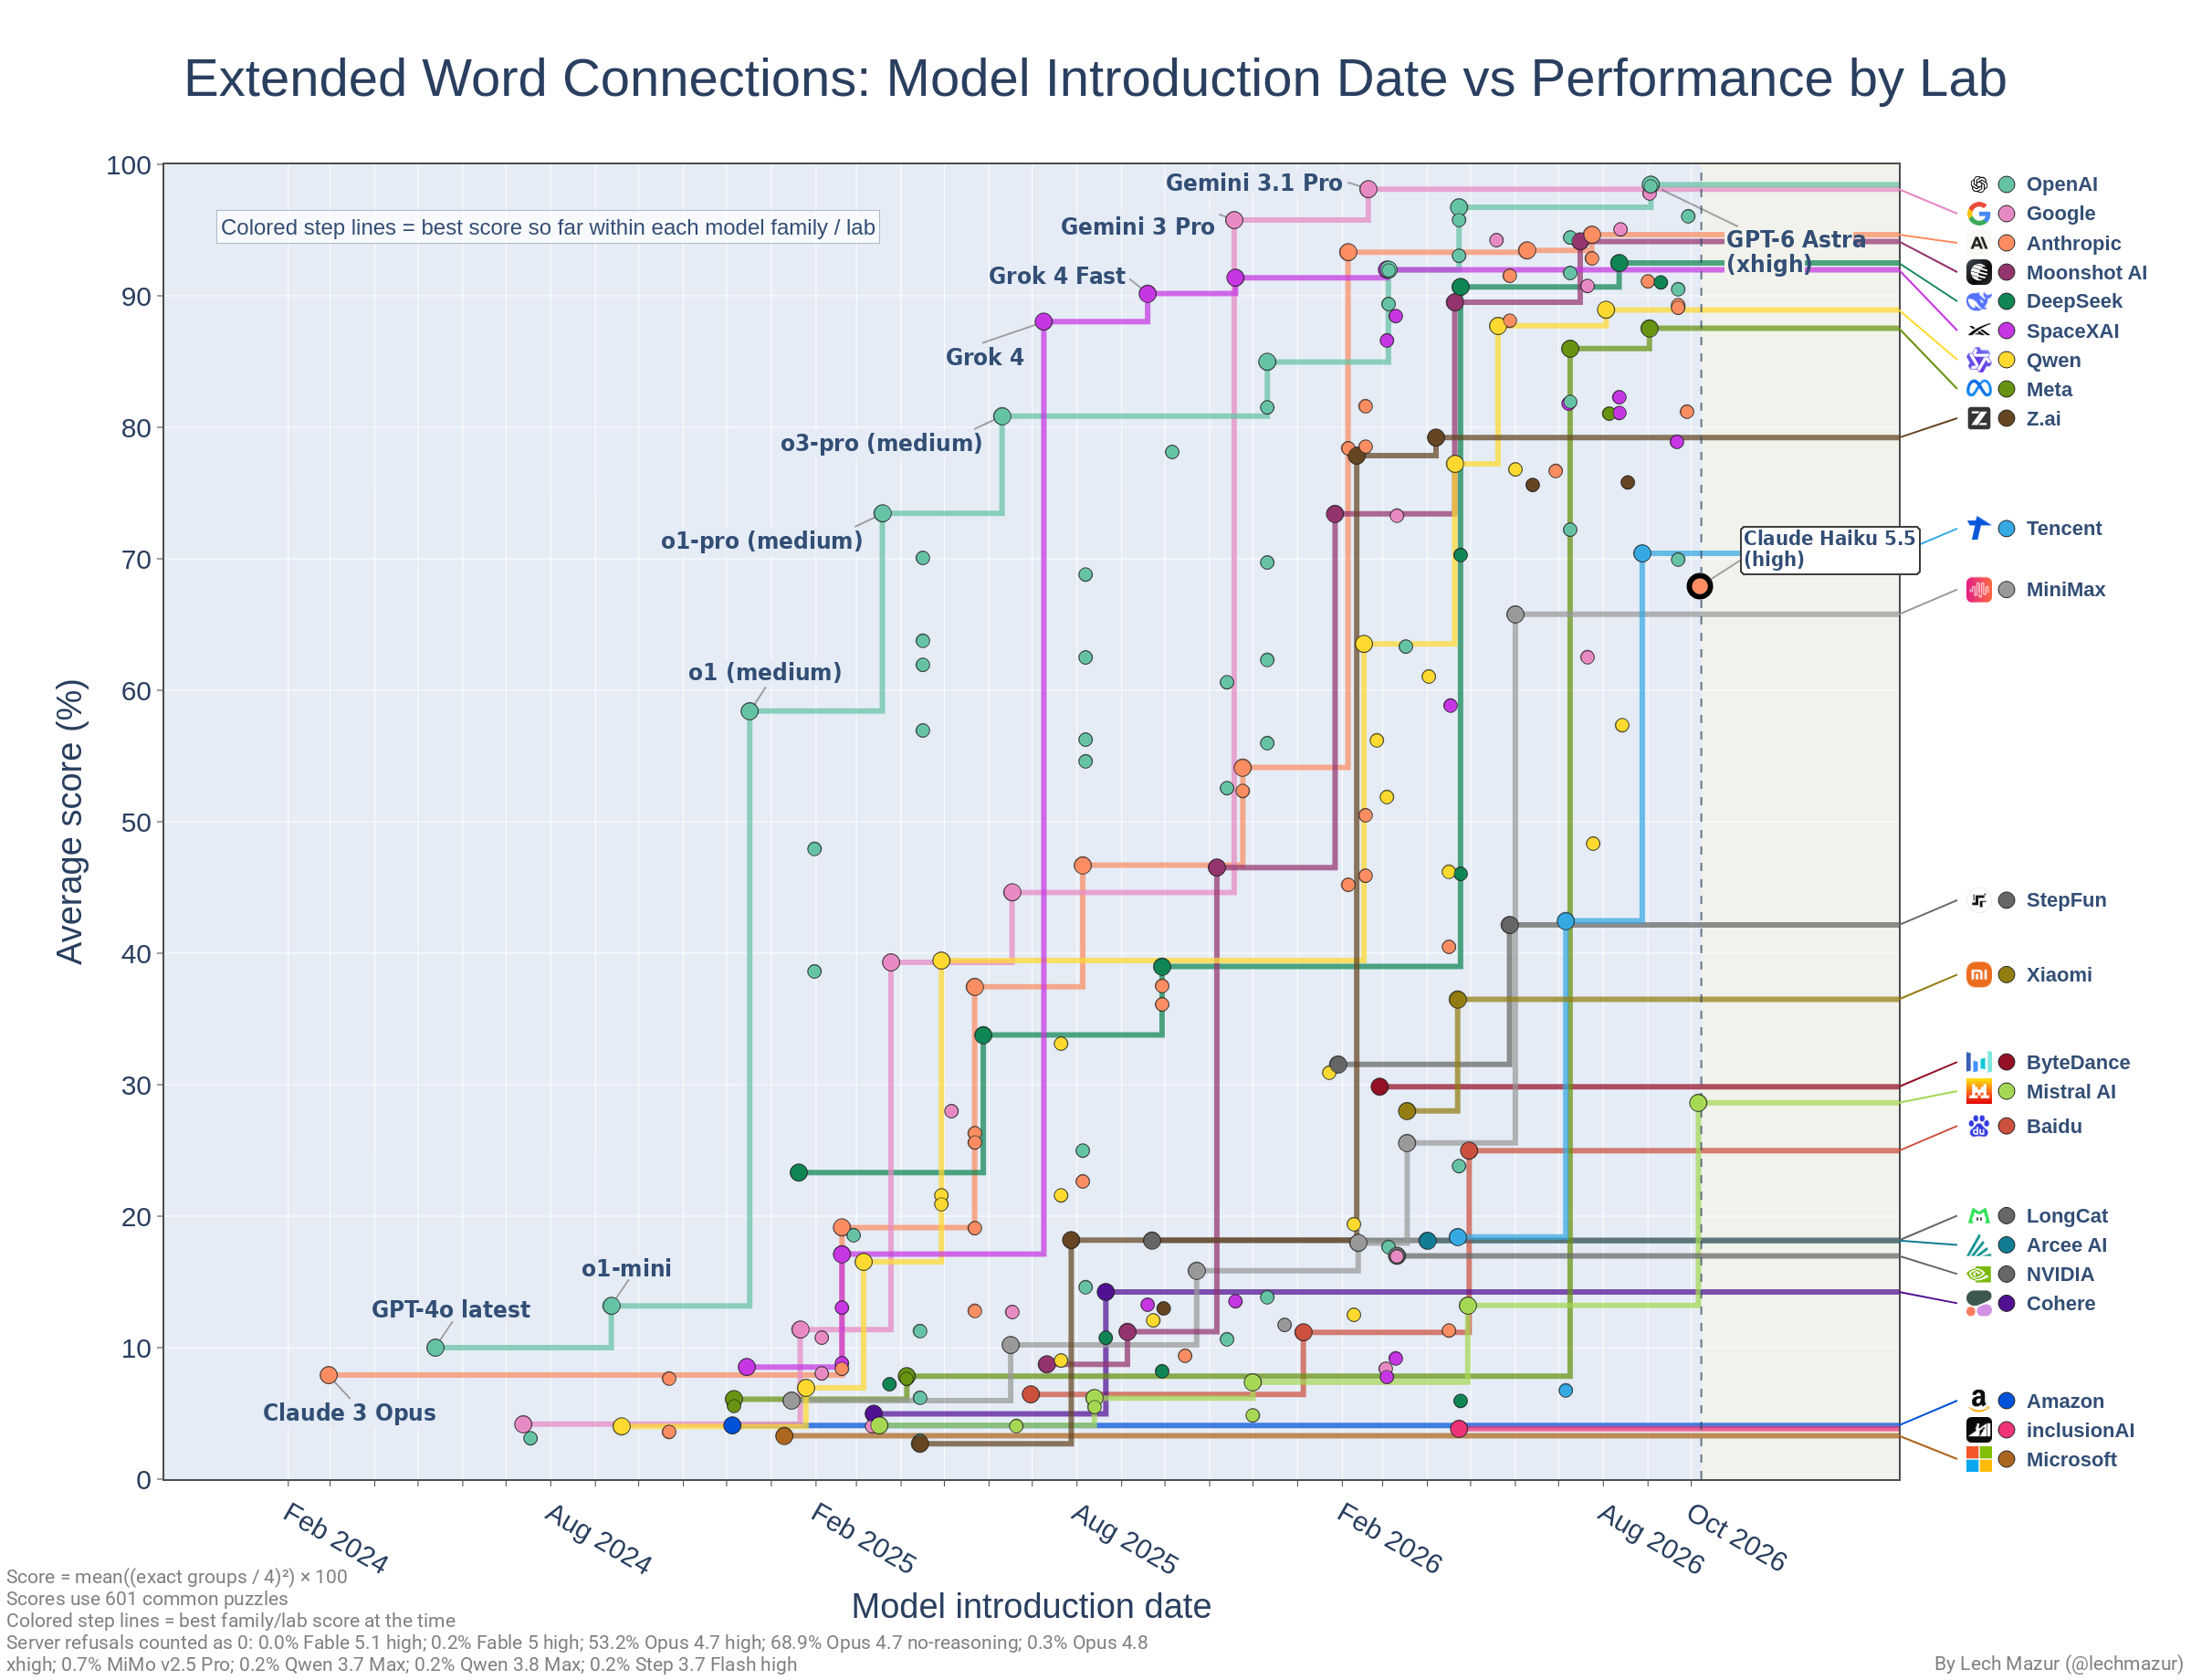
This chart shows score progress over time within each model family on a shared 601-puzzle comparison set. Unlike the charts of current models, it includes every tested model with score and release-date data, including models evaluated on older versions of the benchmark and models omitted from other charts.
Introduction date vs. score
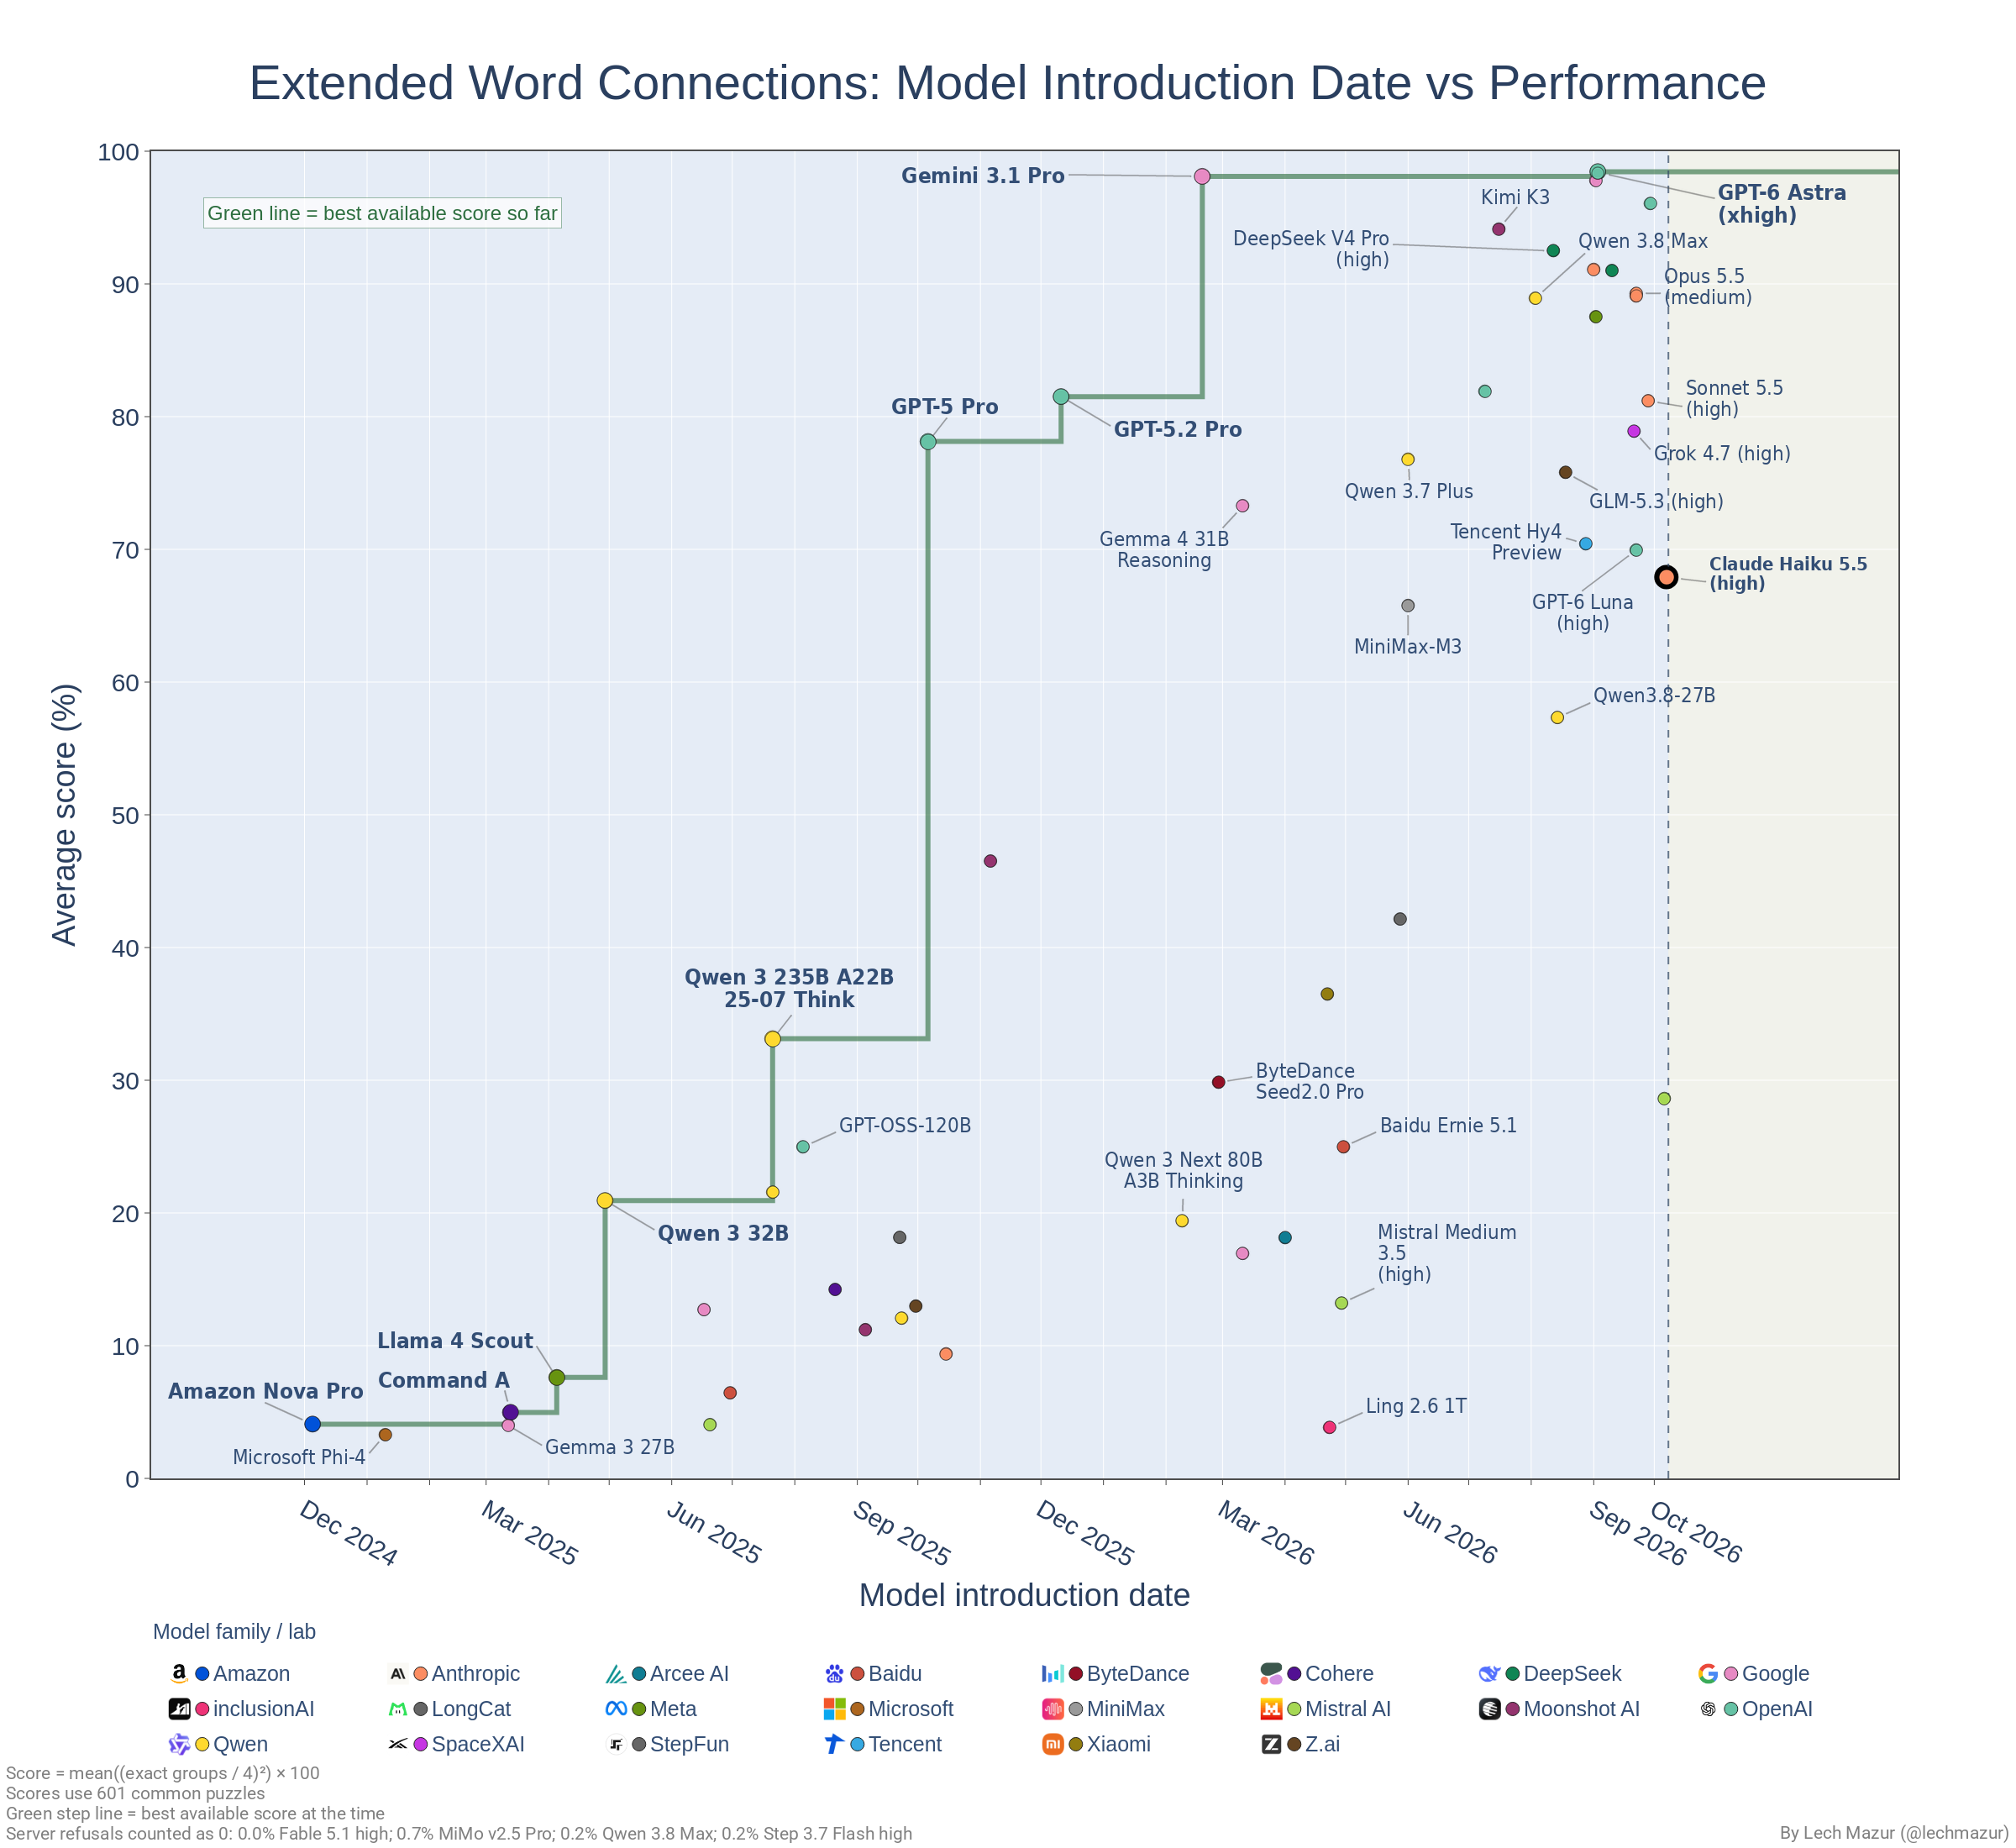
This chart compares benchmark score against model introduction date on the same shared 601-puzzle comparison set.
Cost vs. performance
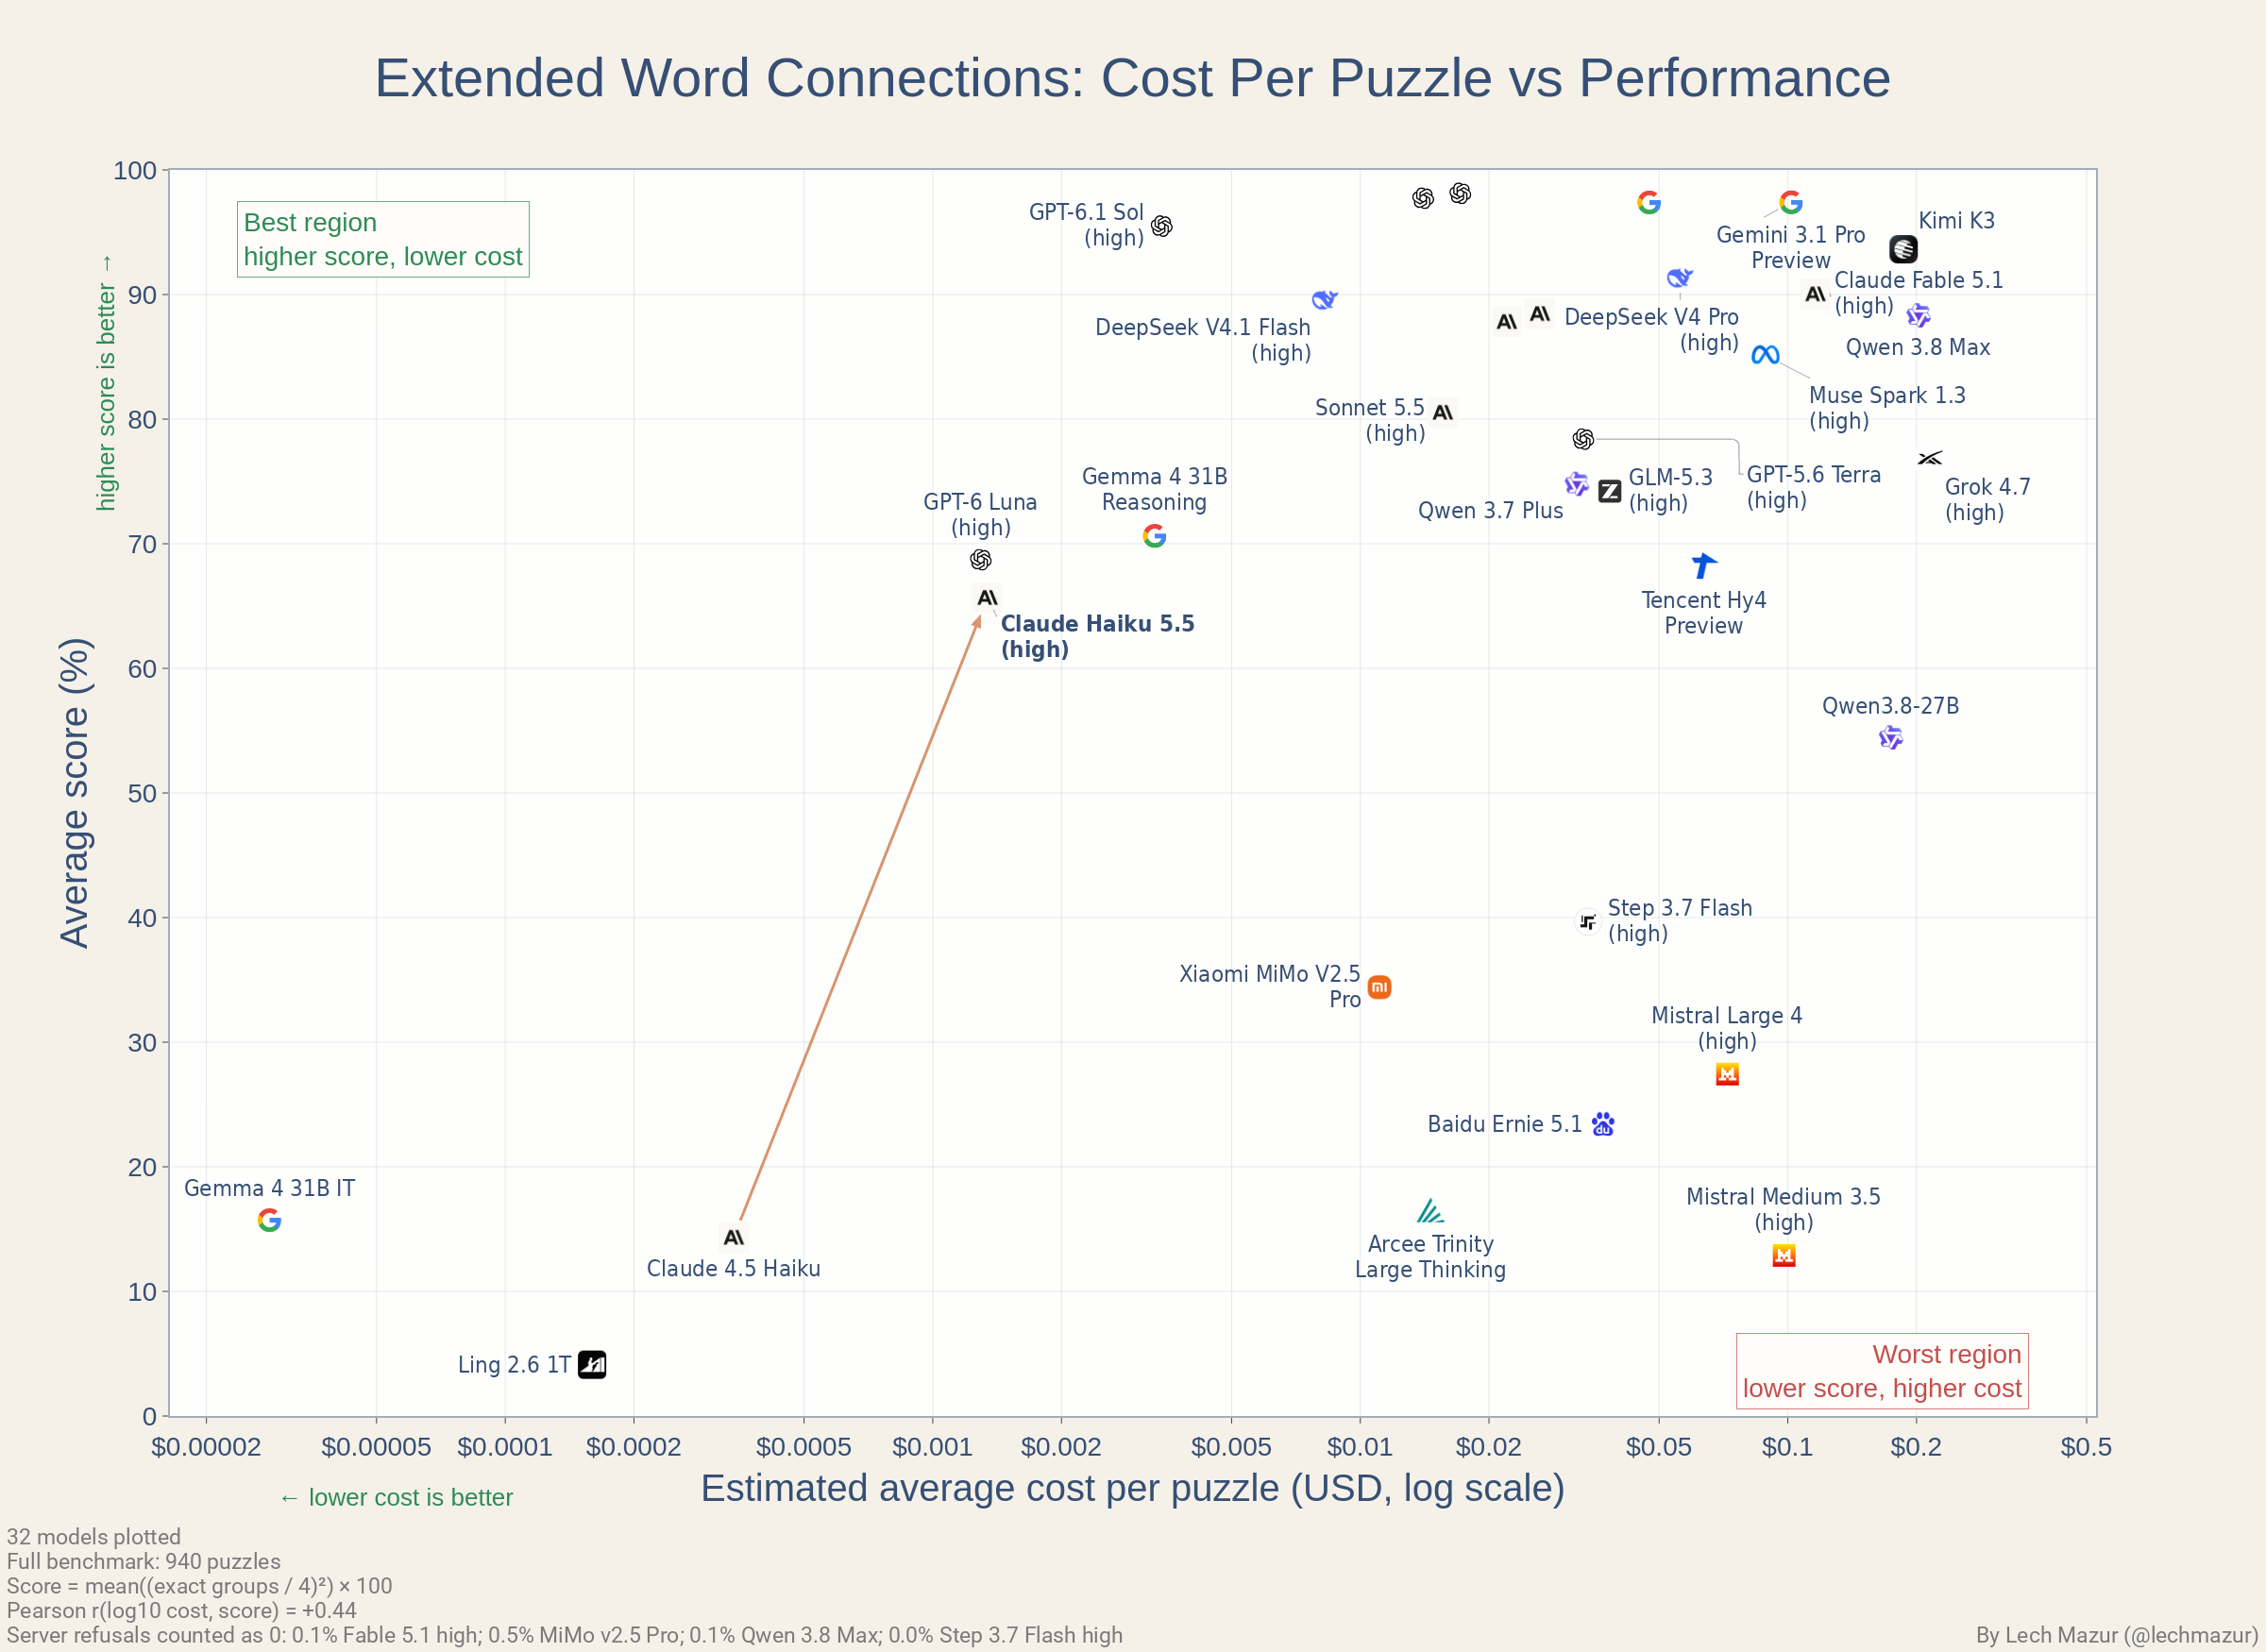
This chart compares estimated average cost per puzzle with the full 940-puzzle benchmark score for current full-coverage models. Costs use recorded token usage and comparable registered display/list prices, not billed totals. Time-varying prices are averaged over their full pricing cycle.
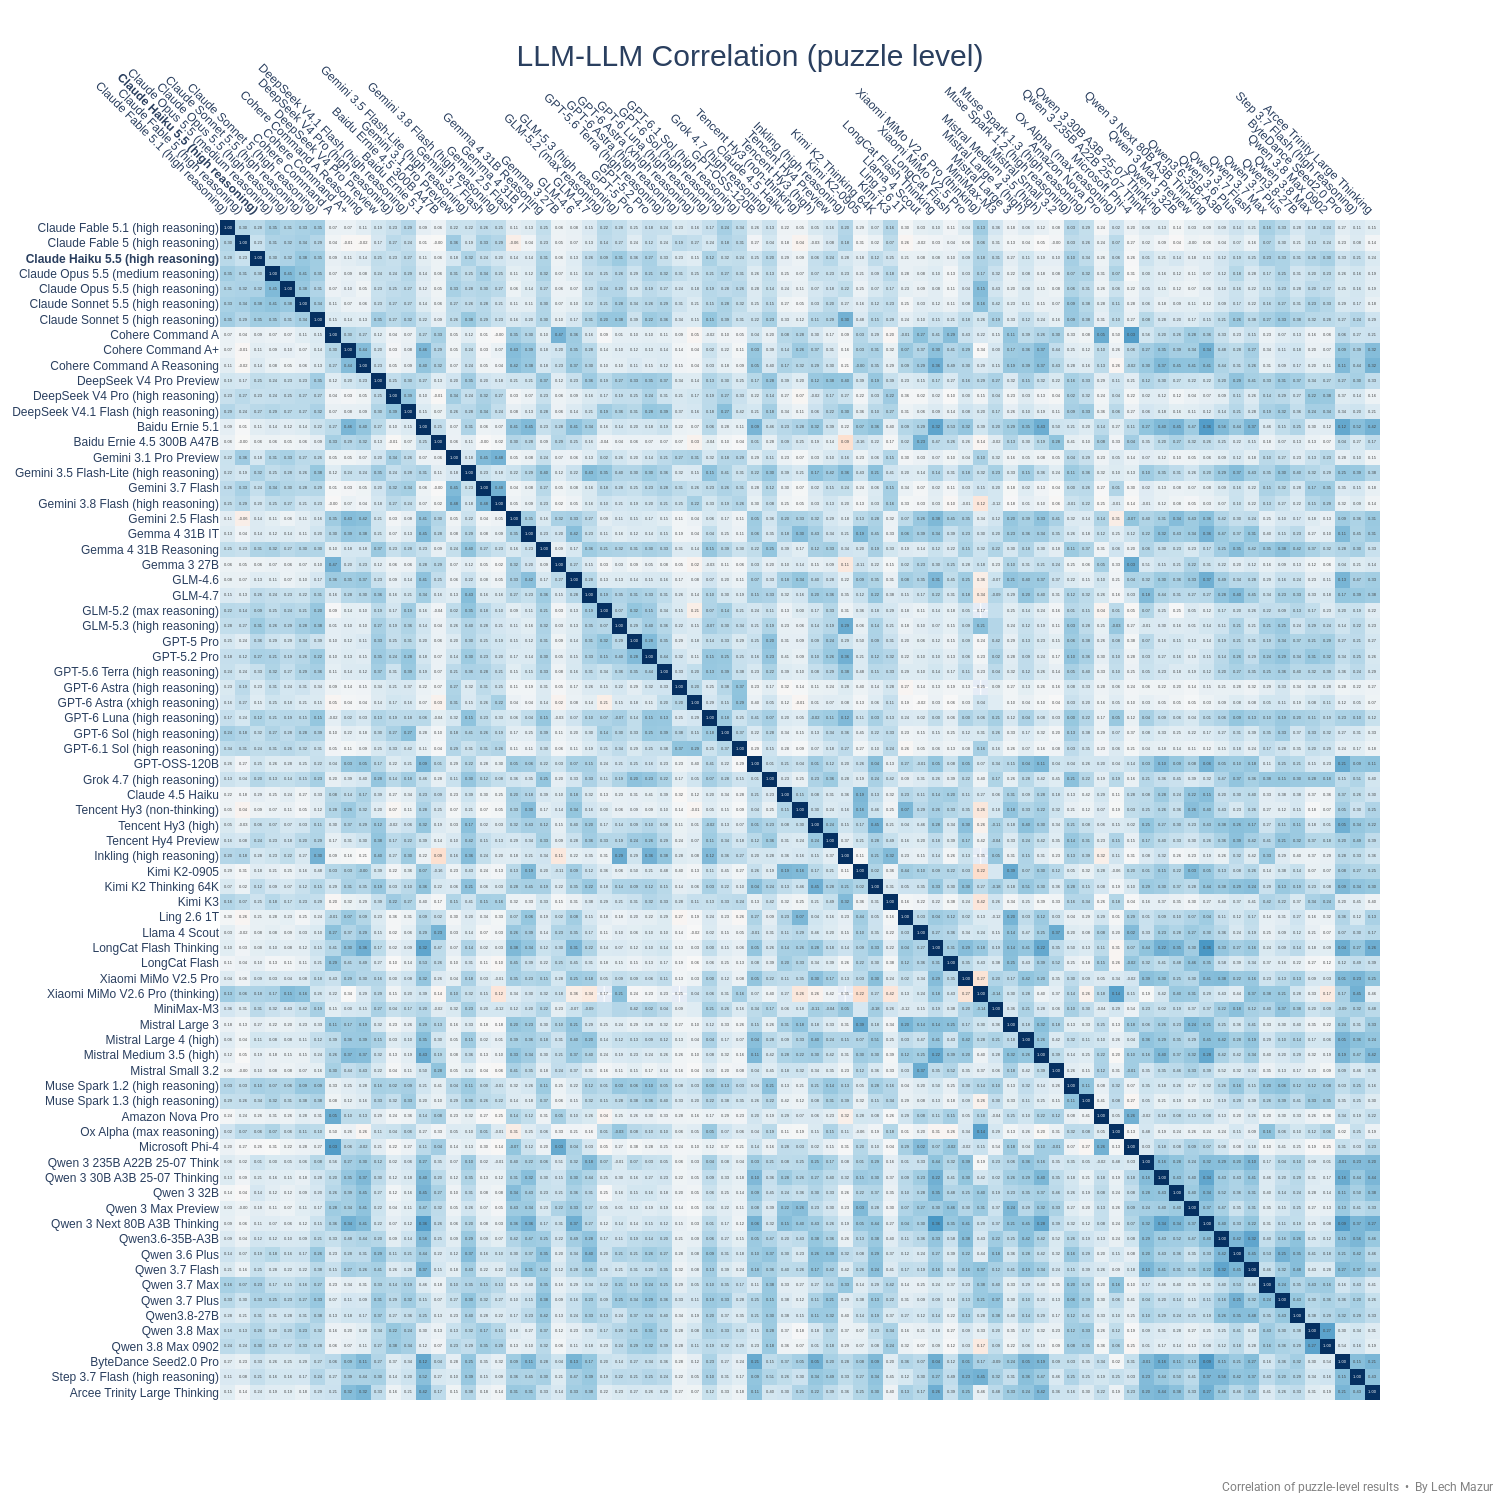
Correlation of puzzle-level results: heatmap
Notes
- Refused or blocked puzzles are scored as 0/4.
- GLM-5.1 is the provider-default thinking run; GLM-5.2 entries with parenthetical reasoning labels use the stated reasoning setting.
- Partial credit follows the scoring rule above, which more heavily rewards complete solves.
- Only one attempt is allowed per puzzle. Humans solving puzzles on the NYT website get four attempts and a notification when they're one step away from the solution.
- This benchmark is not affiliated with the New York Times