SimAgents.Open research
Experiment 03 / Published results

Extended Connections

Can a model find the hidden pattern?

This benchmark evaluates large language models (LLMs) using 940 NYT Connections puzzles, with additional words included to increase difficulty.

To increase difficulty compared to standard NYT Connections puzzles, Extended Connections adds up to four extra trick words to each puzzle. We check that none of the added words fit into any category used in the corresponding puzzle.

It is a focused test of verbal associative reasoning under combinatorial ambiguity: models need lexical and cultural knowledge, wordplay recognition, global constraint solving, and resistance to plausible decoys. It can reflect broader reasoning ability, but it is not a comprehensive measure of general intelligence and does not directly test skills such as software engineering.

This benchmark is not affiliated with the New York Times.

RESULTS AS OF2026-10-08126 models and settingsRead the research ↗
MEASUREPuzzle score (0–100)
DIRECTIONHigher is better
UNCERTAINTYShaded in charts

Published chart

Jump to interactive rankings ↓
Leaderboard
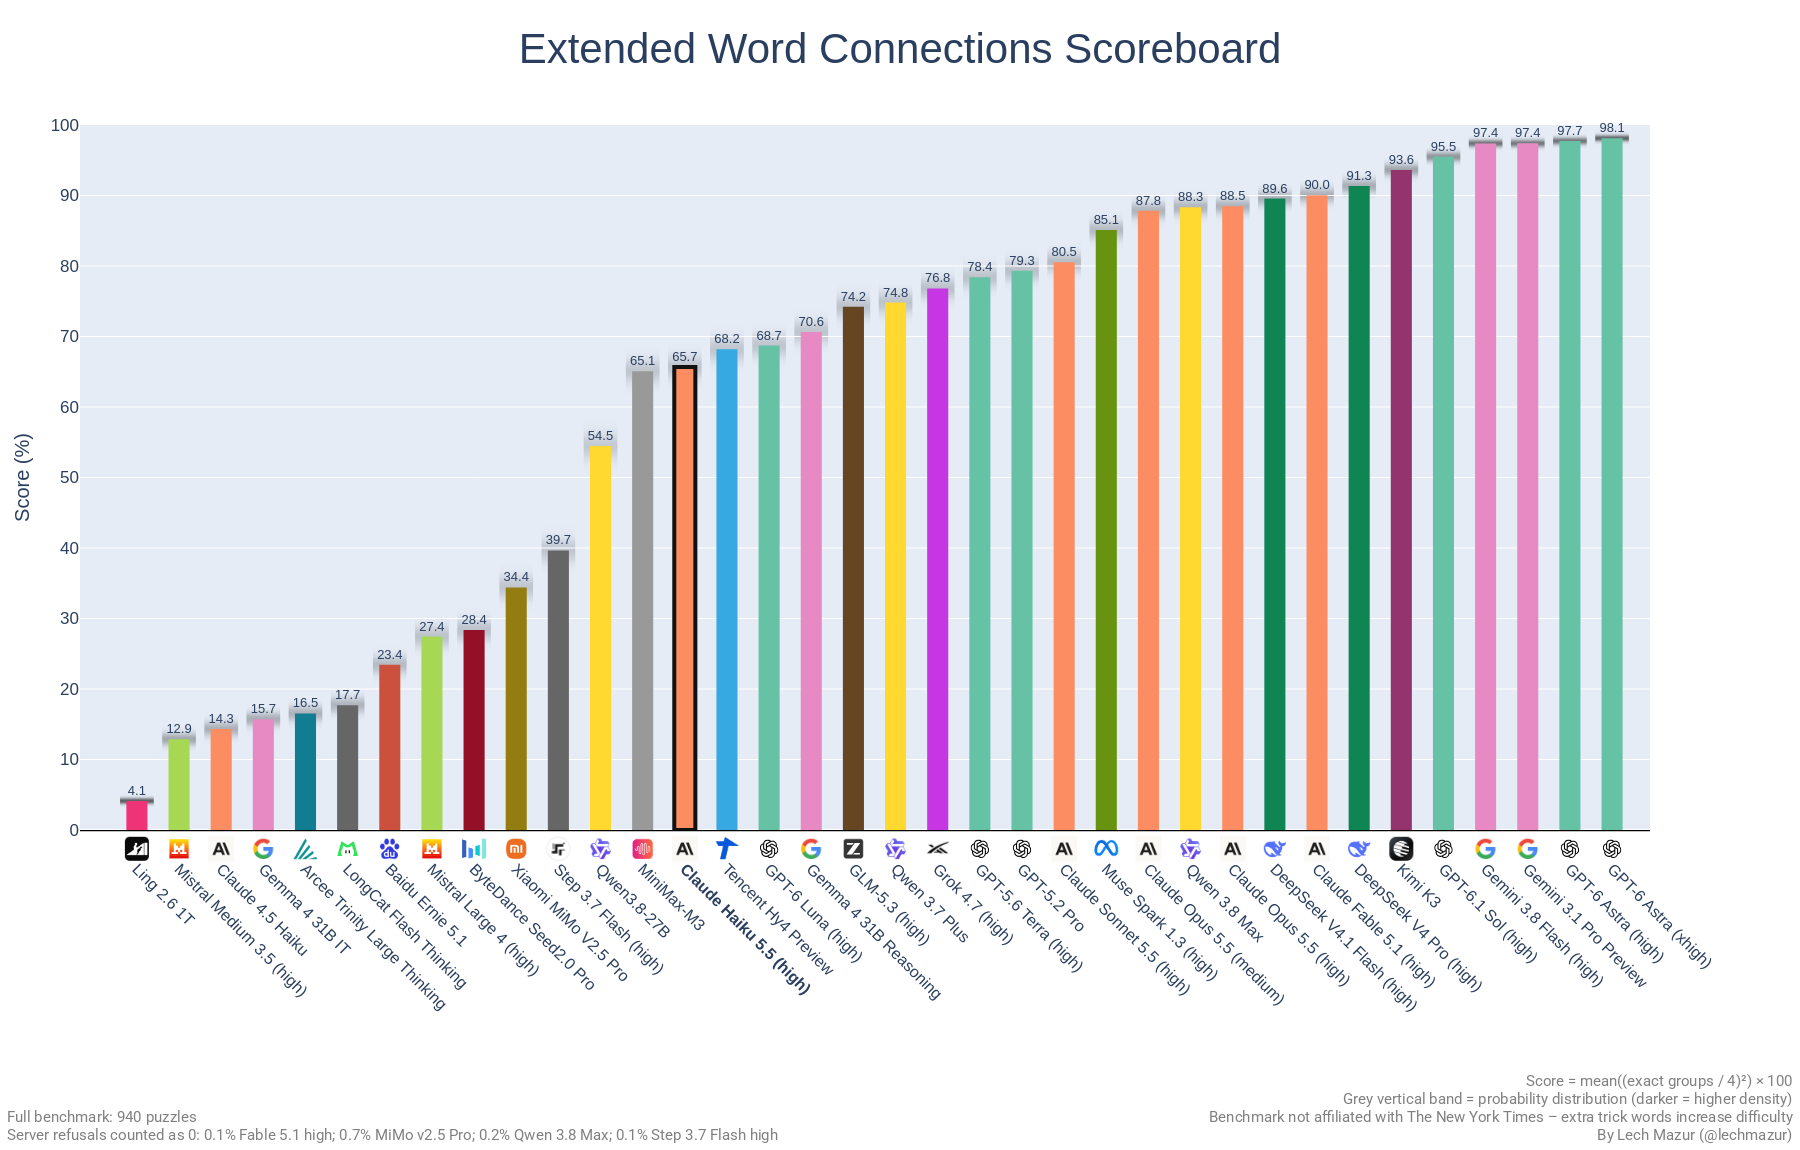
LeaderboardOpen full size ↗

Headline results use a scoring rule that gives more credit for fully solved puzzles: a puzzle with g exact groups contributes (g / 4)², so 0, 1, 2, 3, and 4 groups earn 0%, 6.25%, 25%, 56.25%, and 100%, respectively. The leaderboard score is the mean of those per-puzzle values.

Claude Haiku 5.5 (high) is highlighted in the published full-ranking, newest-100 and cost charts. The published charts show a selection of models. Grey bands show uncertainty; numeric ranges are not given in the tables. The interactive tables include every model tested on all 940 puzzles.

Choose up to 4 models to compare

All 940 puzzles. Every model in this ranking attempted the same puzzles. Newest-100 results and incomplete tests appear separately below.

Extended Connections results as of 2026-10-08, all 940 puzzles
RankModel and settingsDetails
1GPT-6 Astra (xhigh reasoning)98.1
2GPT-6 Astra (high reasoning)97.7
3Gemini 3.1 Pro Preview97.4
4Gemini 3.8 Flash (high reasoning)97.4
5GPT-5.5 (xhigh reasoning)96.2
6GPT-6.1 Sol (high reasoning)95.5
7GPT-5.5 (high reasoning)95.2
8Gemini 3 Pro Preview94.4
9Claude Opus 5 (xhigh reasoning)94.3
10Gemini 3.7 Flash94.0
11GPT-5.6 Sol (xhigh reasoning)93.8
12Kimi K393.6
13Claude Fable 5 (high reasoning)92.7
14Gemini 3.5 Flash92.6
15GPT-5.5 (medium reasoning)92.4
16Claude Opus 5 (high reasoning)92.2
17Claude Opus 4.6 (high reasoning)92.1
18DeepSeek V4 Pro (high reasoning)91.3
19GPT-5.4 (xhigh reasoning)91.3
20Claude Opus 4.8 (xhigh reasoning)91.1
21GPT-5.6 Sol (high reasoning)91.0
22GPT-5.4 (high reasoning)90.6
23GPT-6 Sol (high reasoning)90.1
24Claude Fable 5.1 (high reasoning)90.0
25Grok 4.20 Multi-Agent Exp Beta 030489.6
26DeepSeek V4 Flash89.6
27DeepSeek V4.1 Flash (high reasoning)89.6
28Gemini 3.6 Flash89.0
29Claude Opus 5.5 (high reasoning)88.5
30Claude Opus 4.8 (high reasoning)88.3
31Qwen 3.8 Max88.3
32Claude Opus 5.5 (medium reasoning)87.8
33GPT-5.4 (medium reasoning)87.8
34Grok 4.1 Fast Reasoning87.4
35Kimi K2.687.2
36Grok 4.20 0309 (Reasoning)85.4
37Qwen 3.7 Max85.1
38Muse Spark 1.3 (high reasoning)85.1
39Muse Spark 1.1 (high reasoning)84.9
40Grok 4.20 Reasoning Exp Beta 030483.7
41GPT-5.2 (xhigh reasoning)83.6
42Gemini 3 Flash Preview83.1
43Claude Sonnet 4.6 (high reasoning)80.9
44Claude Sonnet 5.5 (high reasoning)80.5
45Grok 4.6 (xhigh reasoning)80.0
46Grok 4.5 (high reasoning)79.9
47GPT-5.2 Pro79.3
48Muse Spark 1.2 (high reasoning)79.2
49Grok 4.6 (high reasoning)79.0
50GPT-5.6 Terra (high reasoning)78.4
51GLM-5.177.7
52Grok 4.7 (high reasoning)76.8
53Claude Sonnet 4.6 Thinking 32K76.4
54Claude Opus 4.6 Thinking 16K76.4
55Claude Sonnet 5 (high reasoning)75.1
56GLM-574.8
57Qwen 3.7 Plus74.8
58GLM-5.2 (high reasoning)74.3
59GLM-5.3 (high reasoning)74.2
60Qwen 3.6 Max Preview74.1
61Gemma 4 31B Reasoning70.6
62Kimi K2.5 Thinking69.9
63GPT-5.6 Luna (high reasoning)69.4
64GPT-6 Luna (high reasoning)68.7
65Tencent Hy4 Preview68.2
66GPT-5.2 (high reasoning)68.1
67DeepSeek V4 Pro Preview67.3
68Claude Haiku 5.5 (high reasoning)65.7
69MiniMax-M365.1
70GPT-5.4 Mini (xhigh reasoning)61.8
71GPT-5.2 (medium reasoning)60.6
72Gemini 3.5 Flash-Lite (high reasoning)60.4
73Qwen 3.6 Plus60.3
74Qwen3.5-397B-A17B58.9
75Grok 4.355.2
76Qwen3.8-27B54.5
77GPT-5.2 (low reasoning)54.2
78Claude Opus 4.5 Thinking 16K52.5
79Qwen3.5-122B-A10B51.7
80Claude Opus 4.5 (no reasoning)49.4
81Claude Sonnet 4.6 Thinking 16K48.0
82Qwen3.5-27B47.9
83Claude Sonnet 4.6 (no reasoning)44.8
84Qwen 3.7 Flash43.8
85Claude Opus 4.6 (no reasoning)43.2
86Qwen3.6-35B-A3B41.6
87Tencent Hy3 (high)41.2
88Step 3.7 Flash (high reasoning)39.7
89Claude Opus 4.7 (high reasoning)39.0
90Claude Sonnet 4.5 Thinking 16K37.3
91DeepSeek V3.236.7
92Claude Sonnet 4.5 (no reasoning)35.8
93Xiaomi MiMo V2.5 Pro34.4
94Qwen3 Max (2026-01-23)30.1
95Step 3.5 Flash28.4
96ByteDance Seed2.0 Pro28.4
97Mistral Large 4 (high)27.4
98Xiaomi MiMo V2 Pro25.8
99MiniMax-M2.724.7
100Baidu Ernie 5.123.4
101GPT-5.5 (no reasoning)22.0
102GPT-5.4 (no reasoning)17.8
103LongCat Flash Thinking17.7
104Tencent Hy3 Preview17.2
105MiniMax-M2.516.8
106Arcee Trinity Large Thinking16.5
107Gemma 4 31B IT15.7
108Nemotron 3 Super15.4
109MiniMax-M214.8
110GPT-5.2 (no reasoning)14.5
111Claude 4.5 Haiku14.3
112Mistral Medium 3.5 (high)12.9
113Grok 4.1 Fast Non-Reasoning12.3
114Qwen 3 Max Thinking11.8
115MiniMax-M2.111.2
116Claude Opus 4.7 (no reasoning)10.8
117Baidu Ernie 5.010.3
118Grok 4.20 0309 (Non-Reasoning)8.6
119DeepSeek V3.2 (no reasoning)8.2
120Gemini 3.1 Flash-Lite Preview8.2
121Llama 4 Maverick8.0
122Grok 4.20 Non-Reasoning Exp Beta 03047.6
123Mistral Large 37.5
124Tencent Hy3 (non-thinking)6.9
125Mistral Medium 3.16.5
126Ling 2.6 1T4.1

126 of 126 models and settings shown. These rankings apply to this test and publication date.

Inspect the newest 100 puzzles Same models, a separate set of puzzles +

These are the most recent 100 puzzles in the published test. Looking at newer puzzles helps assess whether earlier puzzles might have appeared in a model’s training material. These scores are kept separate from the 940-puzzle ranking above. A lower score on the newest puzzles does not by itself show that older puzzles appeared in training: the earliest puzzles were also easier.

RankModel and settingsPuzzle score (0–100)
1GPT-6 Astra (xhigh reasoning)98.7
2GPT-6 Astra (high reasoning)97.8
3Gemini 3.8 Flash (high reasoning)96.5
4Gemini 3.1 Pro Preview96.1
5GPT-5.5 (xhigh reasoning)96.1
6GPT-6.1 Sol (high reasoning)95.6
7GPT-5.5 (high reasoning)95.2
8Claude Opus 5 (xhigh reasoning)94.5
9GPT-5.6 Sol (xhigh reasoning)94.4
10Claude Fable 5 (high reasoning)93.6
11GPT-5.4 (xhigh reasoning)93.4
12GPT-5.6 Sol (high reasoning)92.7
13Gemini 3 Pro Preview92.3
14Gemini 3.7 Flash92.2
15Claude Opus 4.8 (high reasoning)92.1
16Kimi K392.1
17Claude Opus 5 (high reasoning)91.9
18Gemini 3.5 Flash90.8
19Claude Opus 4.8 (xhigh reasoning)90.6
20Claude Opus 5.5 (high reasoning)90.6
21Qwen 3.8 Max88.9
22GPT-6 Sol (high reasoning)88.8
23Claude Fable 5.1 (high reasoning)88.5
24Gemini 3.6 Flash88.5
25DeepSeek V4 Pro (high reasoning)88.4
26GPT-5.4 (high reasoning)88.4
27Claude Opus 4.6 (high reasoning)88.1
28GPT-5.5 (medium reasoning)87.3
29DeepSeek V4 Flash87.2
30DeepSeek V4.1 Flash (high reasoning)86.1
31Grok 4.20 Multi-Agent Exp Beta 030485.2
32Muse Spark 1.1 (high reasoning)84.8
33GPT-5.4 (medium reasoning)84.4
34Muse Spark 1.3 (high reasoning)83.6
35Claude Opus 5.5 (medium reasoning)83.4
36Kimi K2.680.2
37Claude Sonnet 5.5 (high reasoning)79.1
38Qwen 3.7 Max78.9
39GPT-5.2 (xhigh reasoning)78.6
40Claude Opus 4.6 Thinking 16K78.4
41GLM-5.177.6
42Grok 4.20 0309 (Reasoning)77.4
43Muse Spark 1.2 (high reasoning)77.2
44Grok 4.5 (high reasoning)77.2
45Grok 4.20 Reasoning Exp Beta 030477.1
46Grok 4.6 (xhigh reasoning)77.1
47Grok 4.1 Fast Reasoning75.2
48Grok 4.6 (high reasoning)74.6
49Claude Sonnet 4.6 (high reasoning)74.1
50GLM-5.2 (high reasoning)72.8
51Grok 4.7 (high reasoning)72.8
52GPT-5.6 Terra (high reasoning)72.4
53GLM-5.3 (high reasoning)72.2
54GPT-5.2 Pro71.8
55Qwen 3.7 Plus70.9
56Claude Sonnet 5 (high reasoning)69.9
57Claude Sonnet 4.6 Thinking 32K69.4
58Qwen 3.6 Max Preview69.4
59GLM-567.5
60GPT-5.2 (high reasoning)66.2
61GPT-5.6 Luna (high reasoning)66.1
62Gemma 4 31B Reasoning65.9
63GPT-6 Luna (high reasoning)65.8
64Claude Haiku 5.5 (high reasoning)64.9
65Tencent Hy4 Preview64.2
66Kimi K2.5 Thinking63.7
67MiniMax-M363.4
68GPT-5.4 Mini (xhigh reasoning)62.5
69Gemini 3 Flash Preview61.8
70Gemini 3.5 Flash-Lite (high reasoning)60.7
71DeepSeek V4 Pro Preview59.9
72Qwen 3.6 Plus57.1
73GPT-5.2 (medium reasoning)55.8
74Qwen3.8-27B52.0
75Claude Opus 4.5 Thinking 16K51.6
76Qwen3.5-397B-A17B47.1
77GPT-5.2 (low reasoning)46.4
78Grok 4.345.6
79Qwen3.5-122B-A10B45.4
80Claude Sonnet 4.6 Thinking 16K45.3
81Qwen3.5-27B44.6
82Claude Sonnet 4.5 (no reasoning)43.6
83Claude Sonnet 4.5 Thinking 16K43.0
84Claude Opus 4.5 (no reasoning)42.0
85Tencent Hy3 (high)40.6
86Claude Sonnet 4.6 (no reasoning)40.4
87Claude Opus 4.7 (high reasoning)39.3
88Claude 4.5 Haiku37.5
89Claude Opus 4.6 (no reasoning)37.2
90Qwen3.6-35B-A3B35.5
91Qwen 3.7 Flash35.4
92Step 3.7 Flash (high reasoning)34.2
93Qwen3 Max (2026-01-23)31.6
94Xiaomi MiMo V2.5 Pro31.4
95DeepSeek V3.229.7
96MiniMax-M2.728.6
97ByteDance Seed2.0 Pro28.0
98Mistral Large 4 (high)27.2
99Step 3.5 Flash22.8
100Xiaomi MiMo V2 Pro22.0
101Baidu Ernie 5.120.0
102GPT-5.4 (no reasoning)19.8
103GPT-5.5 (no reasoning)19.1
104Tencent Hy3 Preview18.9
105LongCat Flash Thinking17.3
106Arcee Trinity Large Thinking16.9
107MiniMax-M2.516.2
108GPT-5.2 (no reasoning)15.8
109Gemma 4 31B IT15.7
110Mistral Medium 3.5 (high)14.6
111MiniMax-M2.112.8
112Nemotron 3 Super12.4
113Claude Opus 4.7 (no reasoning)11.9
114MiniMax-M211.9
115Qwen 3 Max Thinking11.6
116Baidu Ernie 5.010.7
117Grok 4.20 0309 (Non-Reasoning)9.4
118Mistral Large 38.9
119Gemini 3.1 Flash-Lite Preview8.9
120Grok 4.1 Fast Non-Reasoning8.8
121Tencent Hy3 (non-thinking)8.2
122Llama 4 Maverick8.1
123Grok 4.20 Non-Reasoning Exp Beta 03047.7
124Mistral Medium 3.17.1
125DeepSeek V3.2 (no reasoning)6.8
126Ling 2.6 1T5.5
Older & incomplete tests 114 results, separate from the main ranking +

These models were tested on fewer than 940 puzzles. Their scores cover different sets of puzzles and should not be compared directly with the main ranking.

Model and settingsPuzzle score (0–100)Puzzles
ByteDance Seed2.1 Pro97.8101 / 940
GLM-5.2 (max reasoning)89.5194 / 940
Sherlock Think Alpha89.0759 / 940
Qwen 3.8 Max 090288.8919 / 940
Grok 4 Fast Reasoning88.0759 / 940
Inkling (high reasoning)88.0136 / 940
Grok 487.8759 / 940
Sonoma Sky Alpha86.5759 / 940
Xiaomi MiMo V2.6 Pro (thinking)84.027 / 940
o3-pro (medium reasoning)81.7759 / 940
GPT-5 Pro77.0759 / 940
GLM-5.2 (max reasoning)75.9211 / 940
o1-pro (medium reasoning)74.6651 / 940
o3 (high reasoning)70.5759 / 940
GPT-5 (high reasoning)67.8759 / 940
o4-mini (high reasoning)64.0759 / 940
Ox Alpha (max reasoning)63.5217 / 940
o3 (medium reasoning)63.0759 / 940
GPT-5 (medium reasoning)61.8759 / 940
o1 (medium reasoning)60.1651 / 940
GPT-5.1 (high reasoning)59.7759 / 940
o4-mini (medium reasoning)58.4651 / 940
GPT-5 mini (medium reasoning)54.9759 / 940
GPT-5 (low reasoning)53.2759 / 940
GPT-5.1 (medium reasoning)51.2759 / 940
o3-mini (high reasoning)49.0651 / 940
GLM-4.747.2767 / 940
Claude Opus 4.1 Thinking 16K45.3759 / 940
Gemini 2.5 Pro44.9759 / 940
Kimi K2 Thinking 64K44.6924 / 940
DeepSeek V4 Flash (thinking)43.9759 / 940
o3-mini (medium reasoning)40.1651 / 940
Gemini 2.5 Pro Exp 03-2540.1651 / 940
Qwen 3 235B A22B39.8759 / 940
Claude Opus 4 Thinking 16K35.2759 / 940
DeepSeek R1 05/2833.6759 / 940
Qwen 3 235B A22B 25-07 Think31.6759 / 940
Gemini 2.5 Pro Preview 05-0628.1651 / 940
Claude Sonnet 4 Thinking 16K26.4759 / 940
Claude Sonnet 4 Thinking 64K26.0651 / 940
DeepSeek R124.4651 / 940
GPT-OSS-120B24.1759 / 940
Claude Opus 4.1 (no reasoning)21.7759 / 940
Qwen 3 30B A3B21.2759 / 940
Qwen 3 32B21.0759 / 940
Qwen 3 30B A3B 25-07 Thinking20.9759 / 940
Claude 3.7 Sonnet Thinking 16K19.7651 / 940
Claude Opus 4 (no reasoning)19.7759 / 940
GPT-4.5 Preview19.2651 / 940
Qwen 3 Next 80B A3B Thinking18.5759 / 940
Qwen QwQ-32B 16K17.8651 / 940
Grok 3 Mini Beta (high)17.2759 / 940
GLM-4.517.0759 / 940
o1-mini14.1651 / 940
Grok 3 Mini Beta (low)14.0651 / 940
GPT-5 (minimal reasoning)13.9759 / 940
Claude Sonnet 4 (no reasoning)13.7759 / 940
Claude Opus 4.6 Thinking 32K13.698 / 940
Cohere Command A Reasoning13.3759 / 940
Gemini 2.5 Flash12.8759 / 940
Grok 4 Fast Non-Reasoning12.5759 / 940
GLM-4.612.5759 / 940
Sherlock Dash Alpha12.2759 / 940
Quasar Alpha12.1651 / 940
Gemini 2.0 Flash Think Exp 01-2112.0649 / 940
Cohere Command A+12.0898 / 940
GPT-4o Mar 202511.8759 / 940
Qwen 3 Max Preview11.6759 / 940
Gemini 2.0 Pro Exp 02-0511.2651 / 940
Kimi K2-090511.0759 / 940
GPT-4.110.8759 / 940
Sonoma Dusk Alpha10.6759 / 940
MiniMax-M110.5688 / 940
GPT-4o Feb 202510.3651 / 940
Polaris Alpha10.2759 / 940
DeepSeek V3.1 Non-Think10.1759 / 940
GPT-5.1 (no reasoning)10.0759 / 940
Grok 3 Beta (no reasoning)9.0759 / 940
Kimi K28.9759 / 940
Claude 3.7 Sonnet8.7651 / 940
Gemini 1.5 Pro (Sept)8.7601 / 940
Qwen 3 235B A22B 25-07 Instruct8.6759 / 940
GPT-4o 2024-11-208.6601 / 940
Grok 2 12-128.5651 / 940
Gemini 2.0 Flash8.3651 / 940
Claude 3 Opus8.2650 / 940
Claude 3.5 Sonnet 2024-10-228.1651 / 940
GPT-4o 2024-08-067.6601 / 940
Llama 4 Scout7.6759 / 940
Qwen 2.5 Max7.6651 / 940
DeepSeek V3-03247.4759 / 940
Llama 3.1 405B6.7651 / 940
Baidu Ernie 4.5 300B A47B6.5759 / 940
DeepSeek V4 Flash6.2651 / 940
GPT-4.1 mini6.1759 / 940
Llama 3.3 70B5.9651 / 940
MiniMax-Text-015.9759 / 940
Mistral Medium 3.15.5759 / 940
LongCat Flash5.2660 / 940
Cohere Command A5.0759 / 940
Mistral Large 34.8759 / 940
Mistral Small 3.24.3759 / 940
Gemma 2 27B4.3651 / 940
Mistral Small 3.14.2651 / 940
Gemma 3 27B4.2759 / 940
Amazon Nova Pro4.1759 / 940
Qwen 2.5 72B4.0759 / 940
Claude 3.5 Haiku3.8759 / 940
Microsoft Phi-43.4759 / 940
GPT-4o mini3.4759 / 940
Mistral Small 33.0601 / 940
GPT-4.1 nano2.8759 / 940
GLM4-32B-04142.7759 / 940
Claude 3 Haiku0.7601 / 940
From the published research

Findings and method.

Results as of 2026-10-08. Read the original publication ↗

Model comparisons

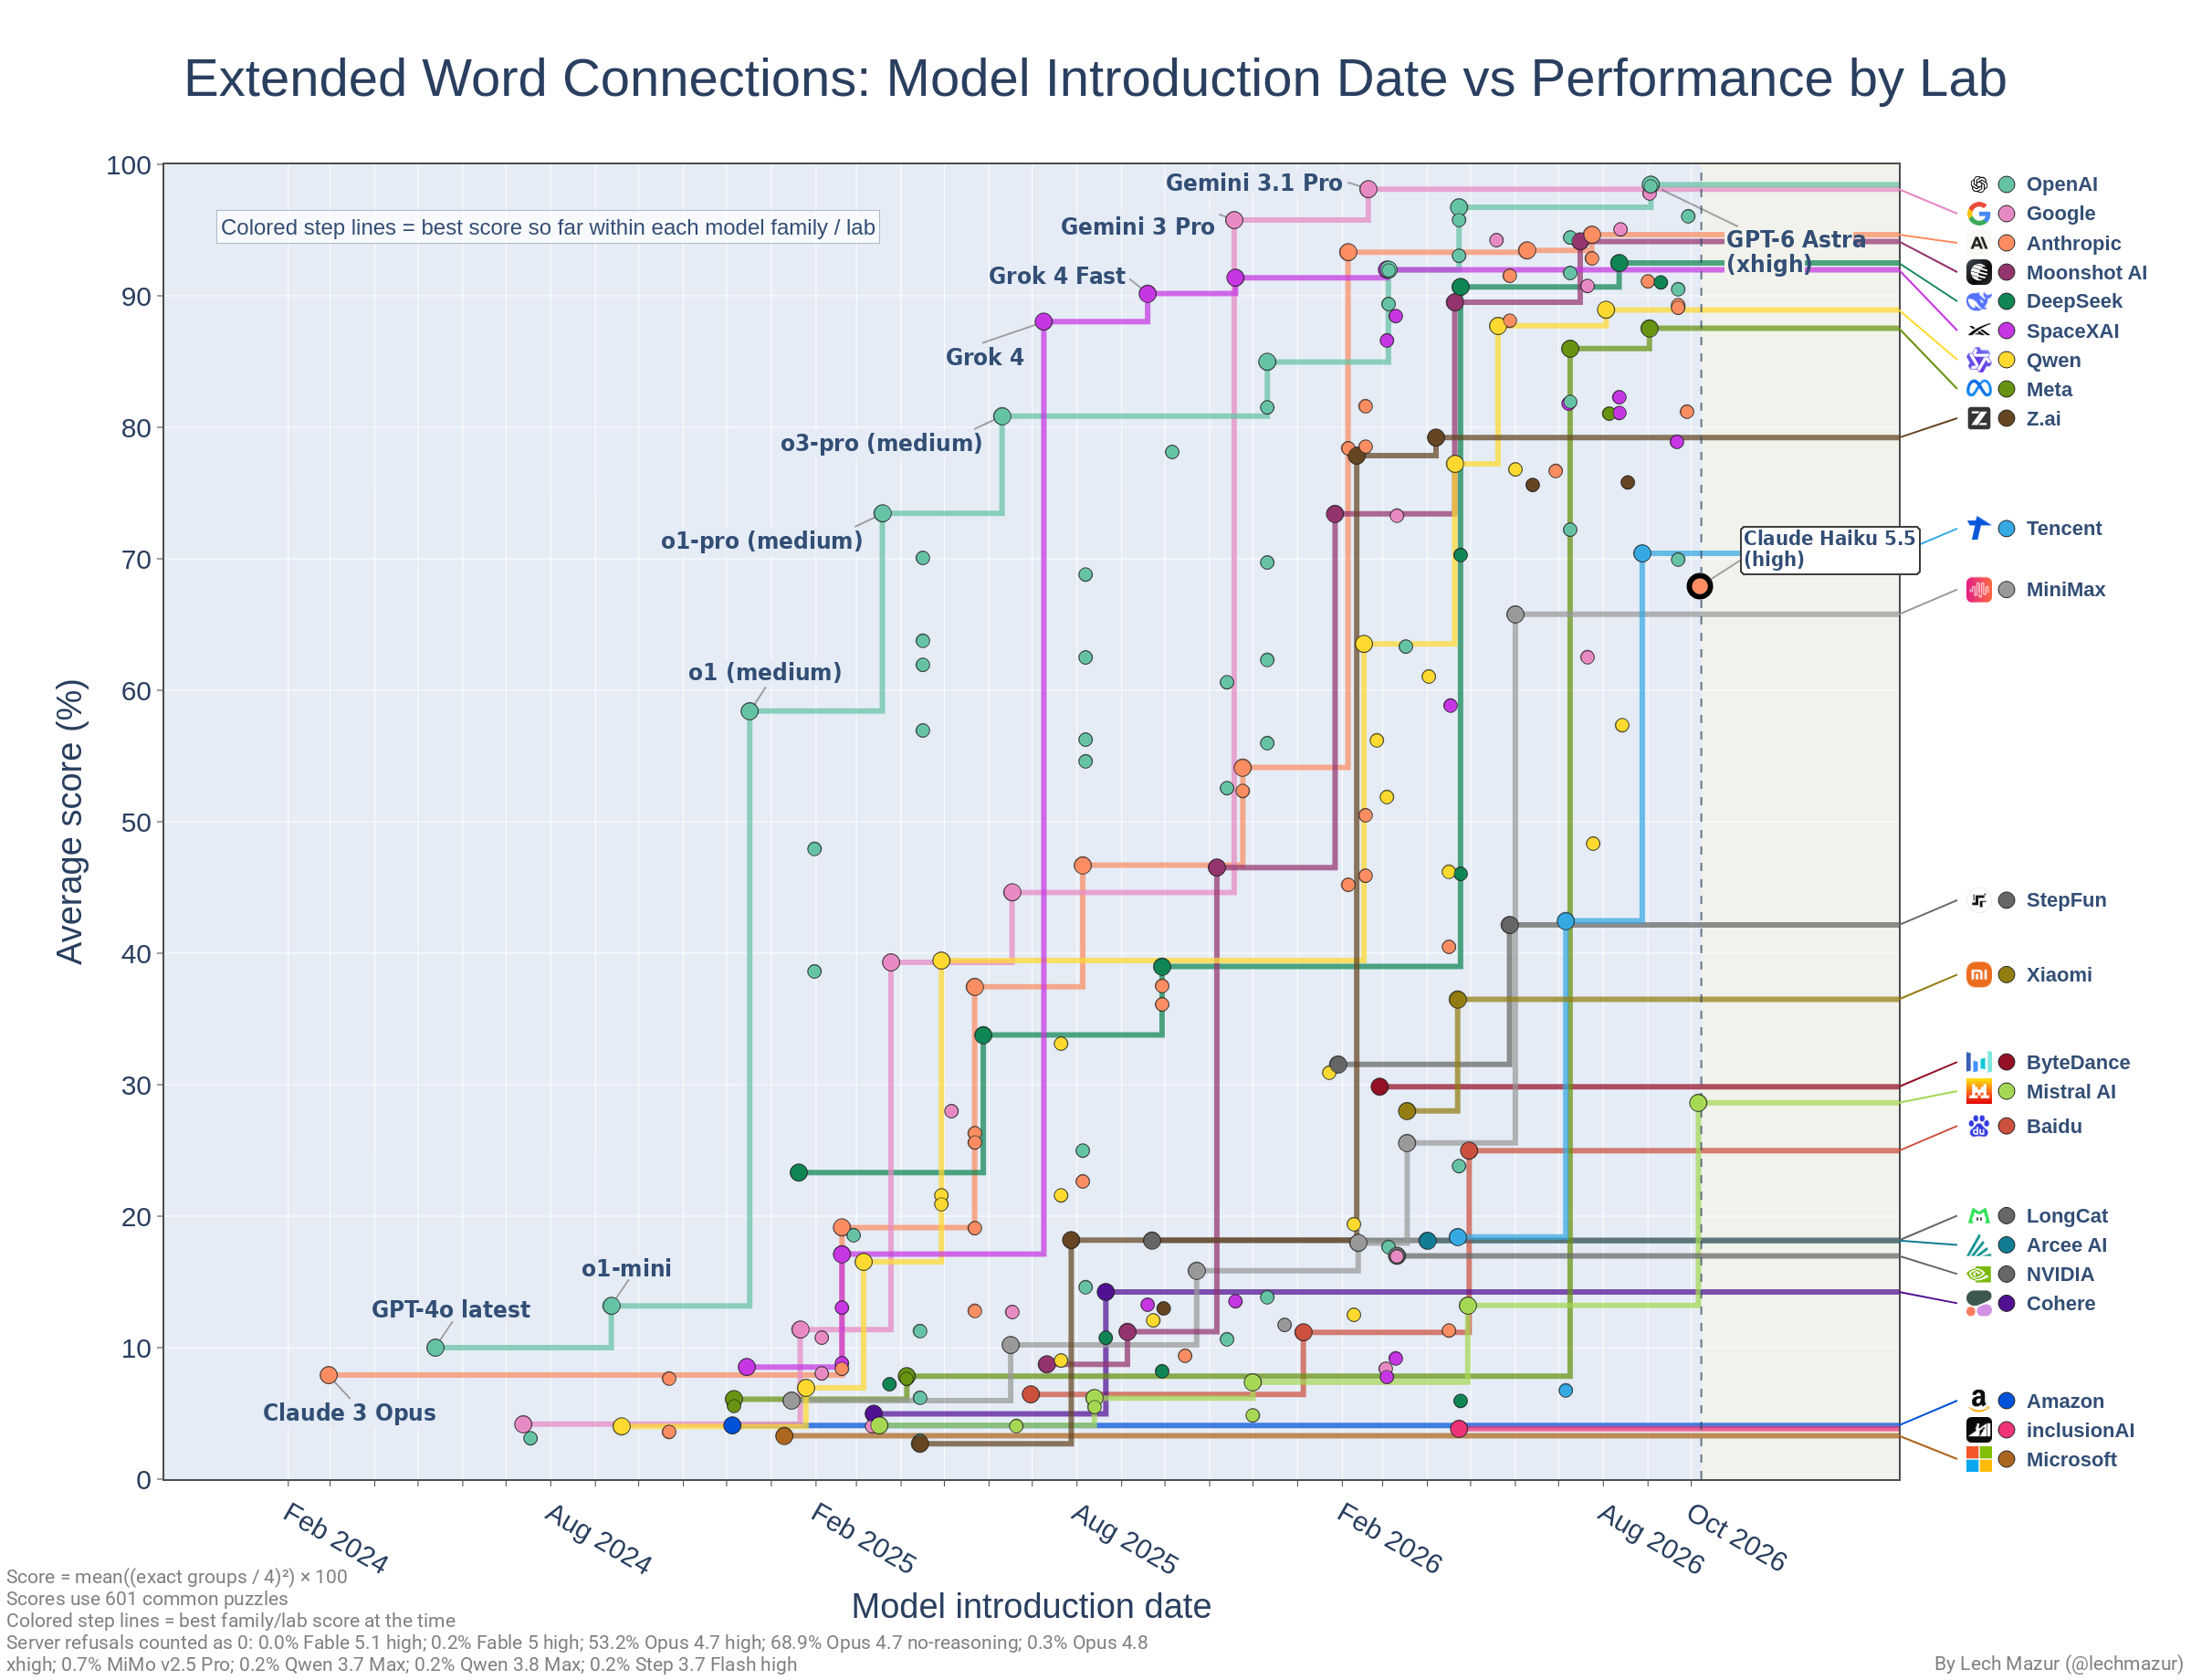
Model family progress

This chart shows score progress over time within each model family on a shared 601-puzzle comparison set. Unlike the charts of current models, it includes every tested model with score and release-date data, including models evaluated on older versions of the benchmark and models omitted from other charts.
Model family progress
Model family progressOpen full size ↗

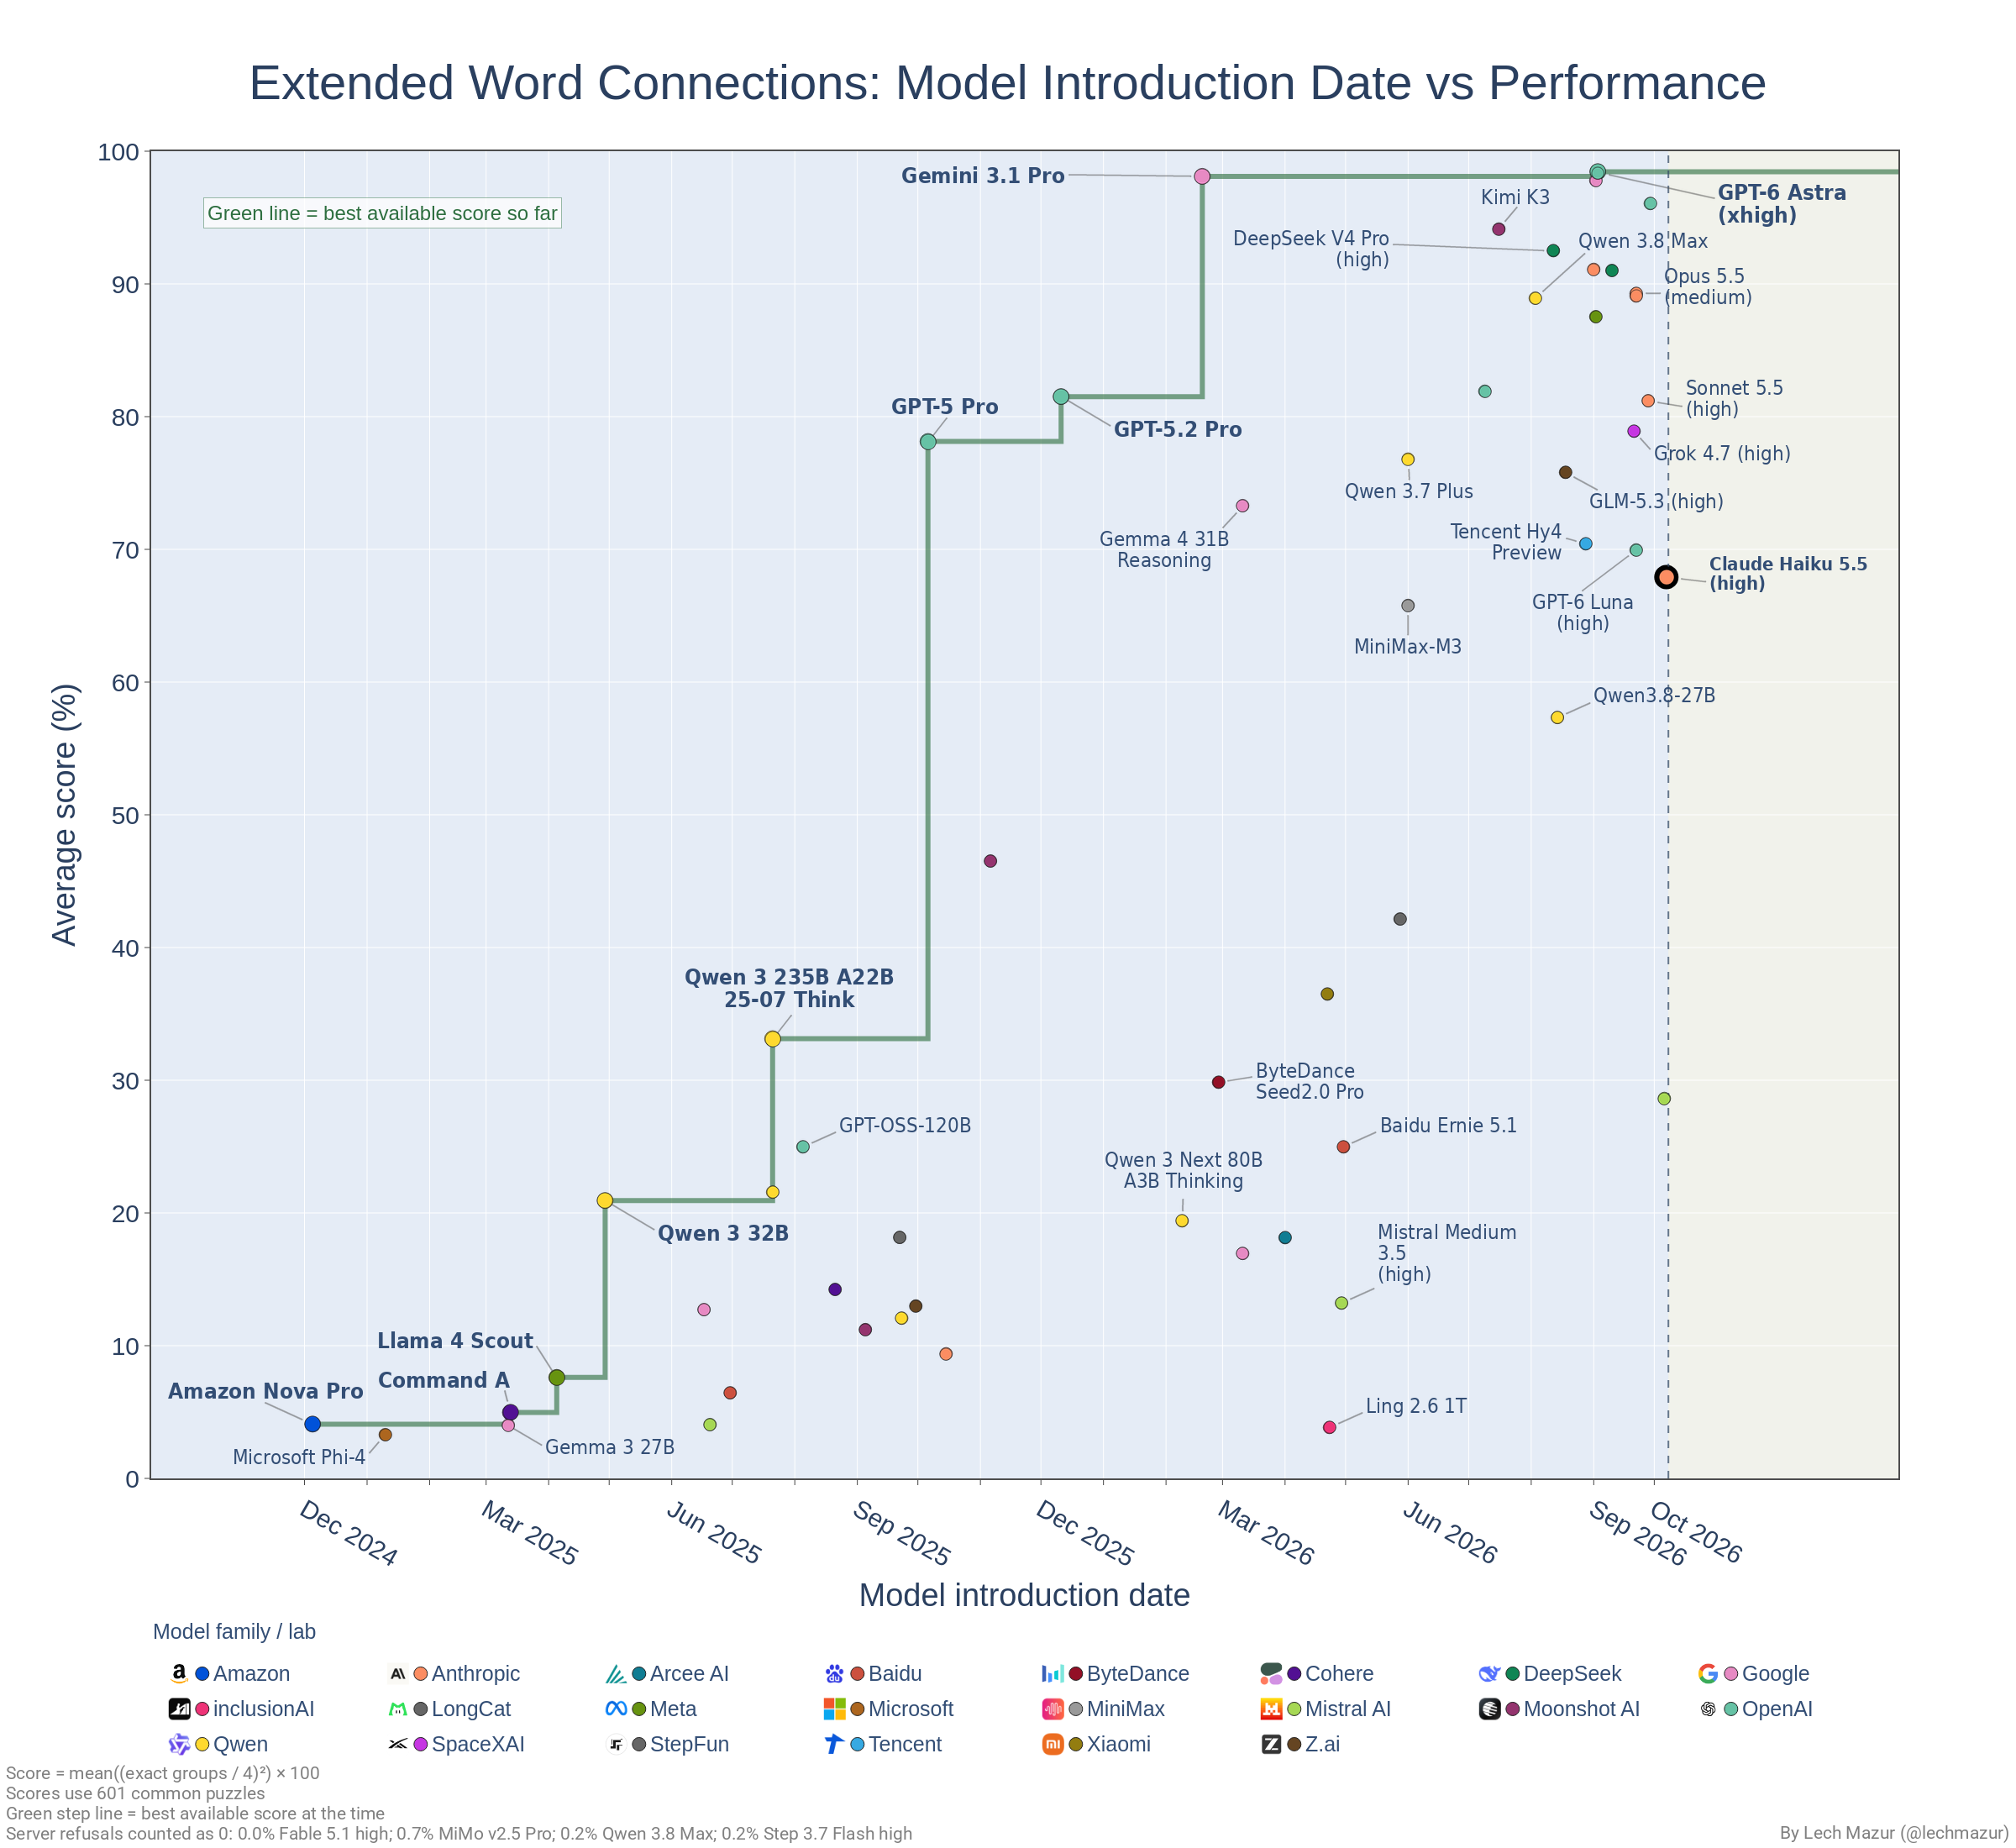
Introduction date vs. score

This chart compares benchmark score against model introduction date on the same shared 601-puzzle comparison set.
Introduction date vs. score
Introduction date vs. scoreOpen full size ↗

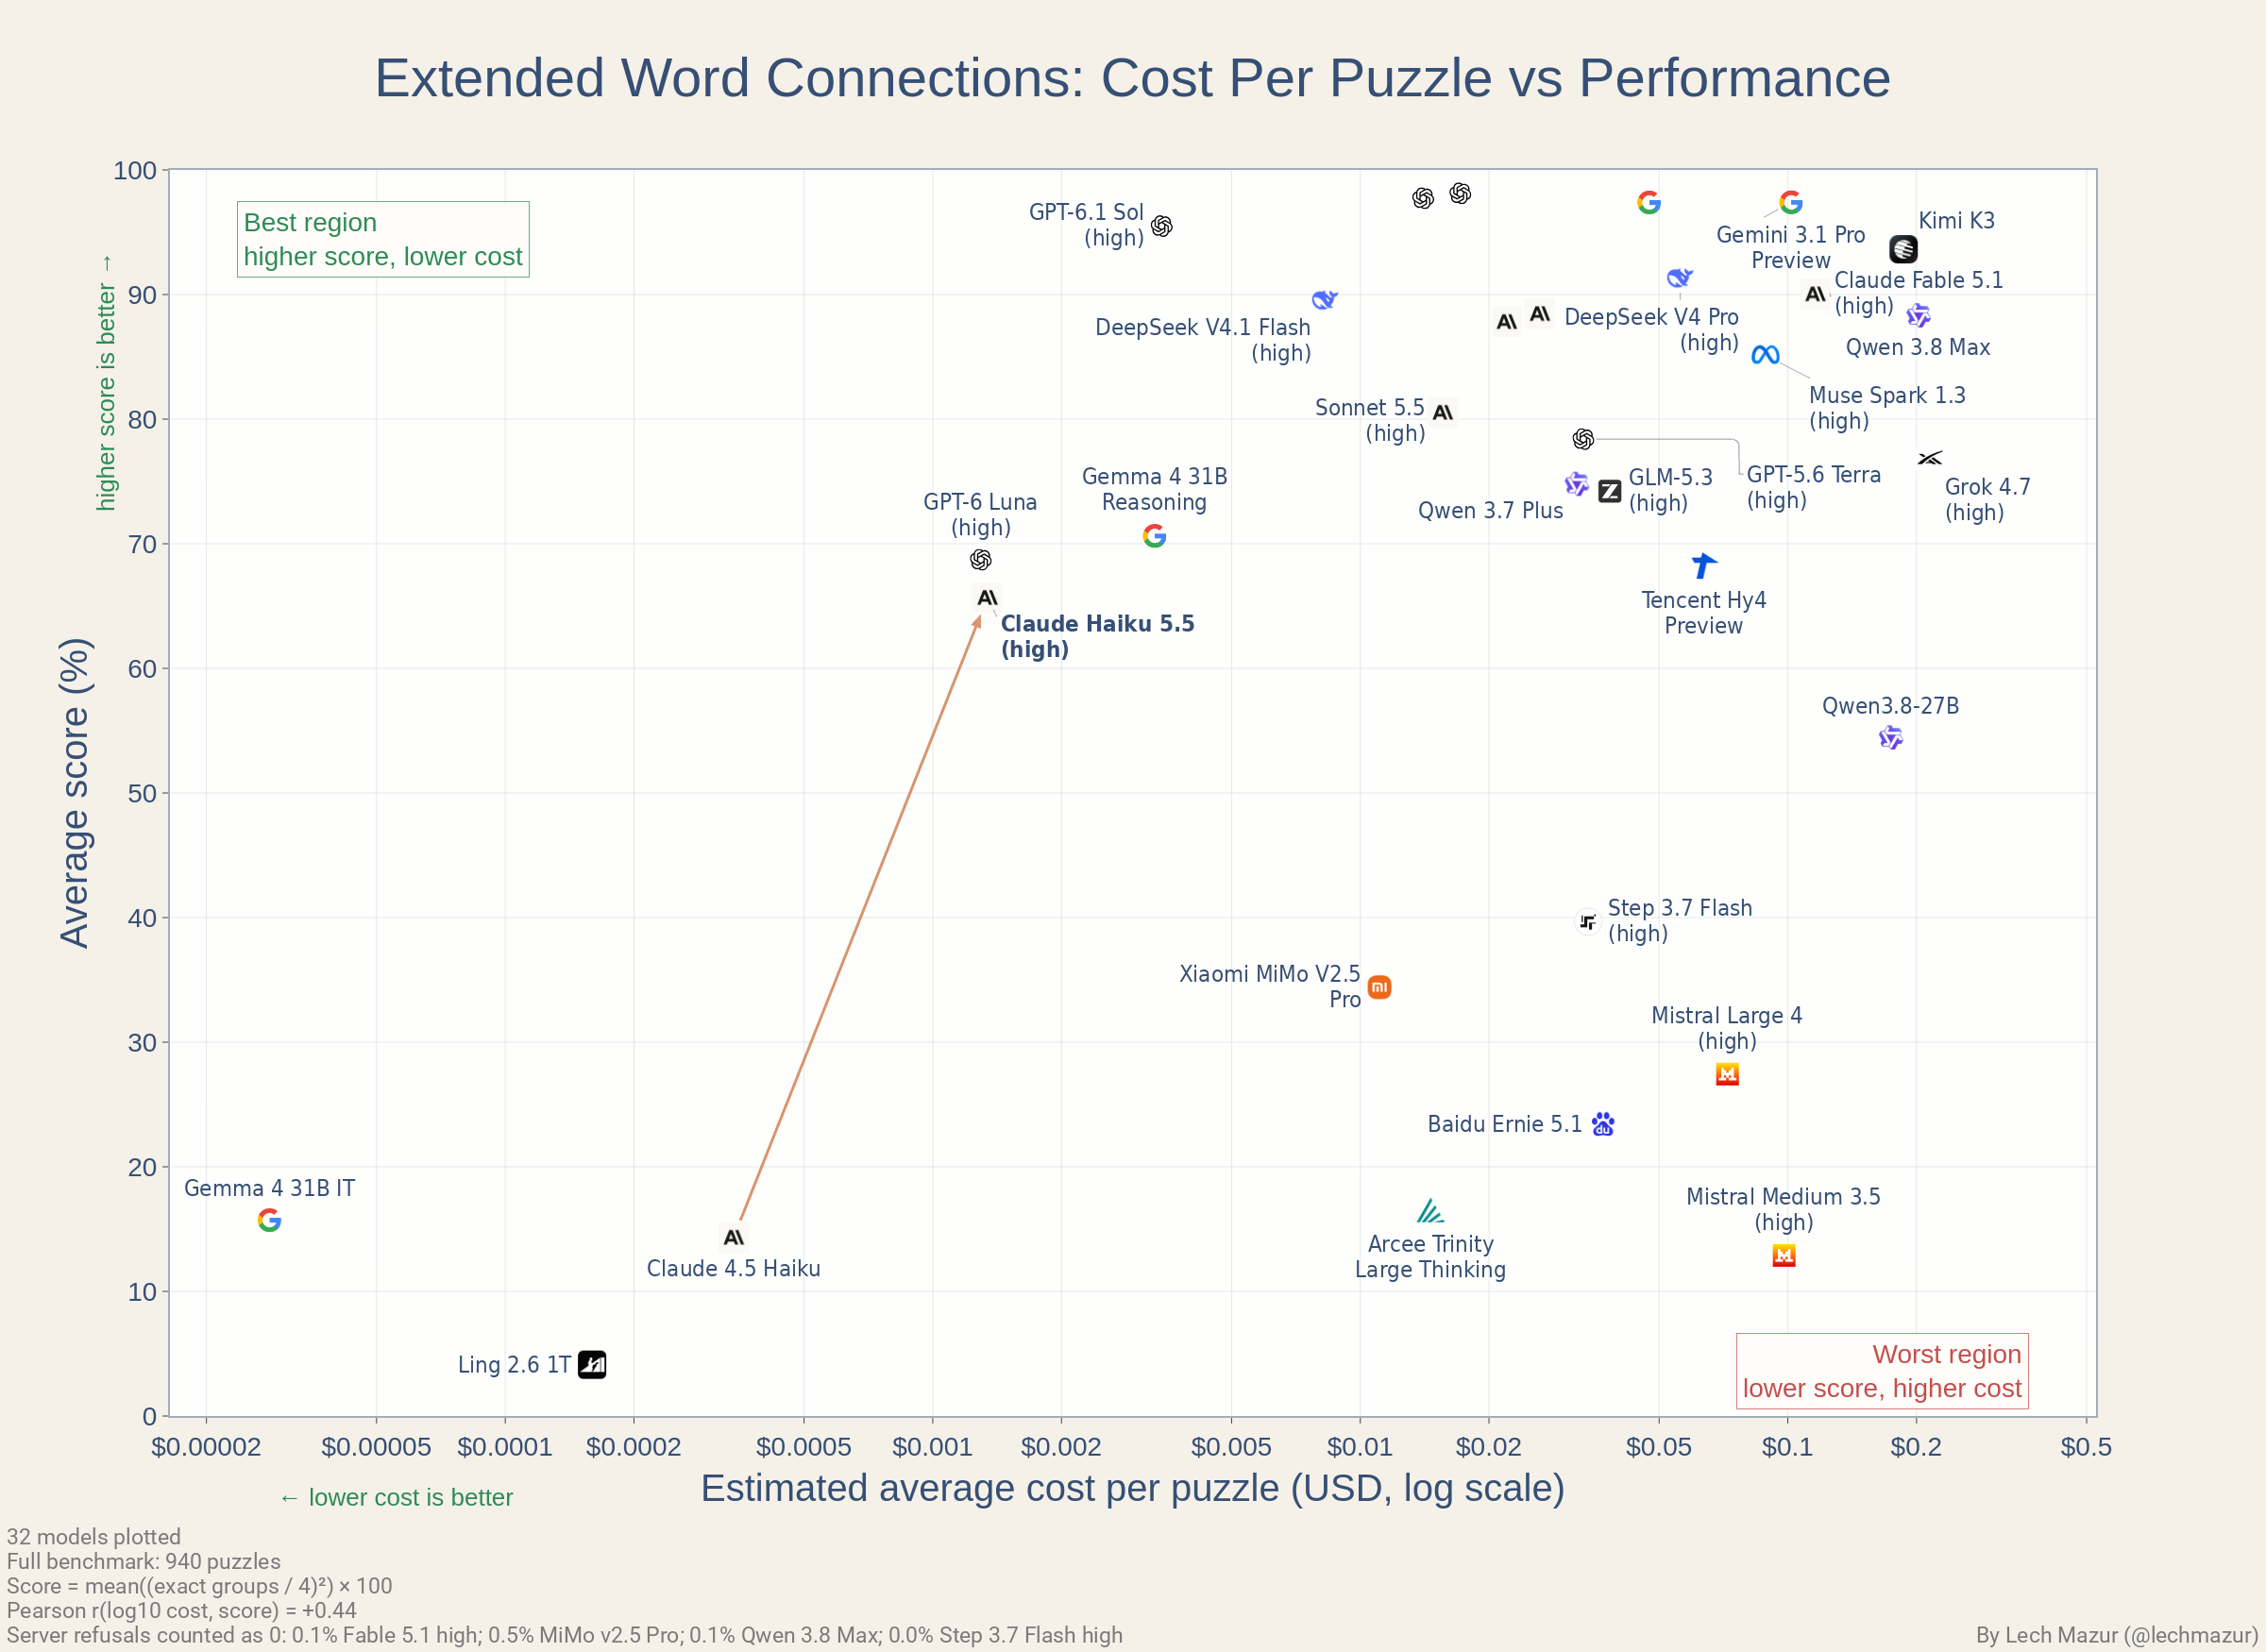
Cost vs. performance

This chart compares estimated average cost per puzzle with the full 940-puzzle benchmark score for current full-coverage models. Costs use recorded token usage and comparable registered display/list prices, not billed totals. Time-varying prices are averaged over their full pricing cycle.
Cost vs. performance
Cost vs. performanceOpen full size ↗

Correlation of puzzle-level results: heatmap
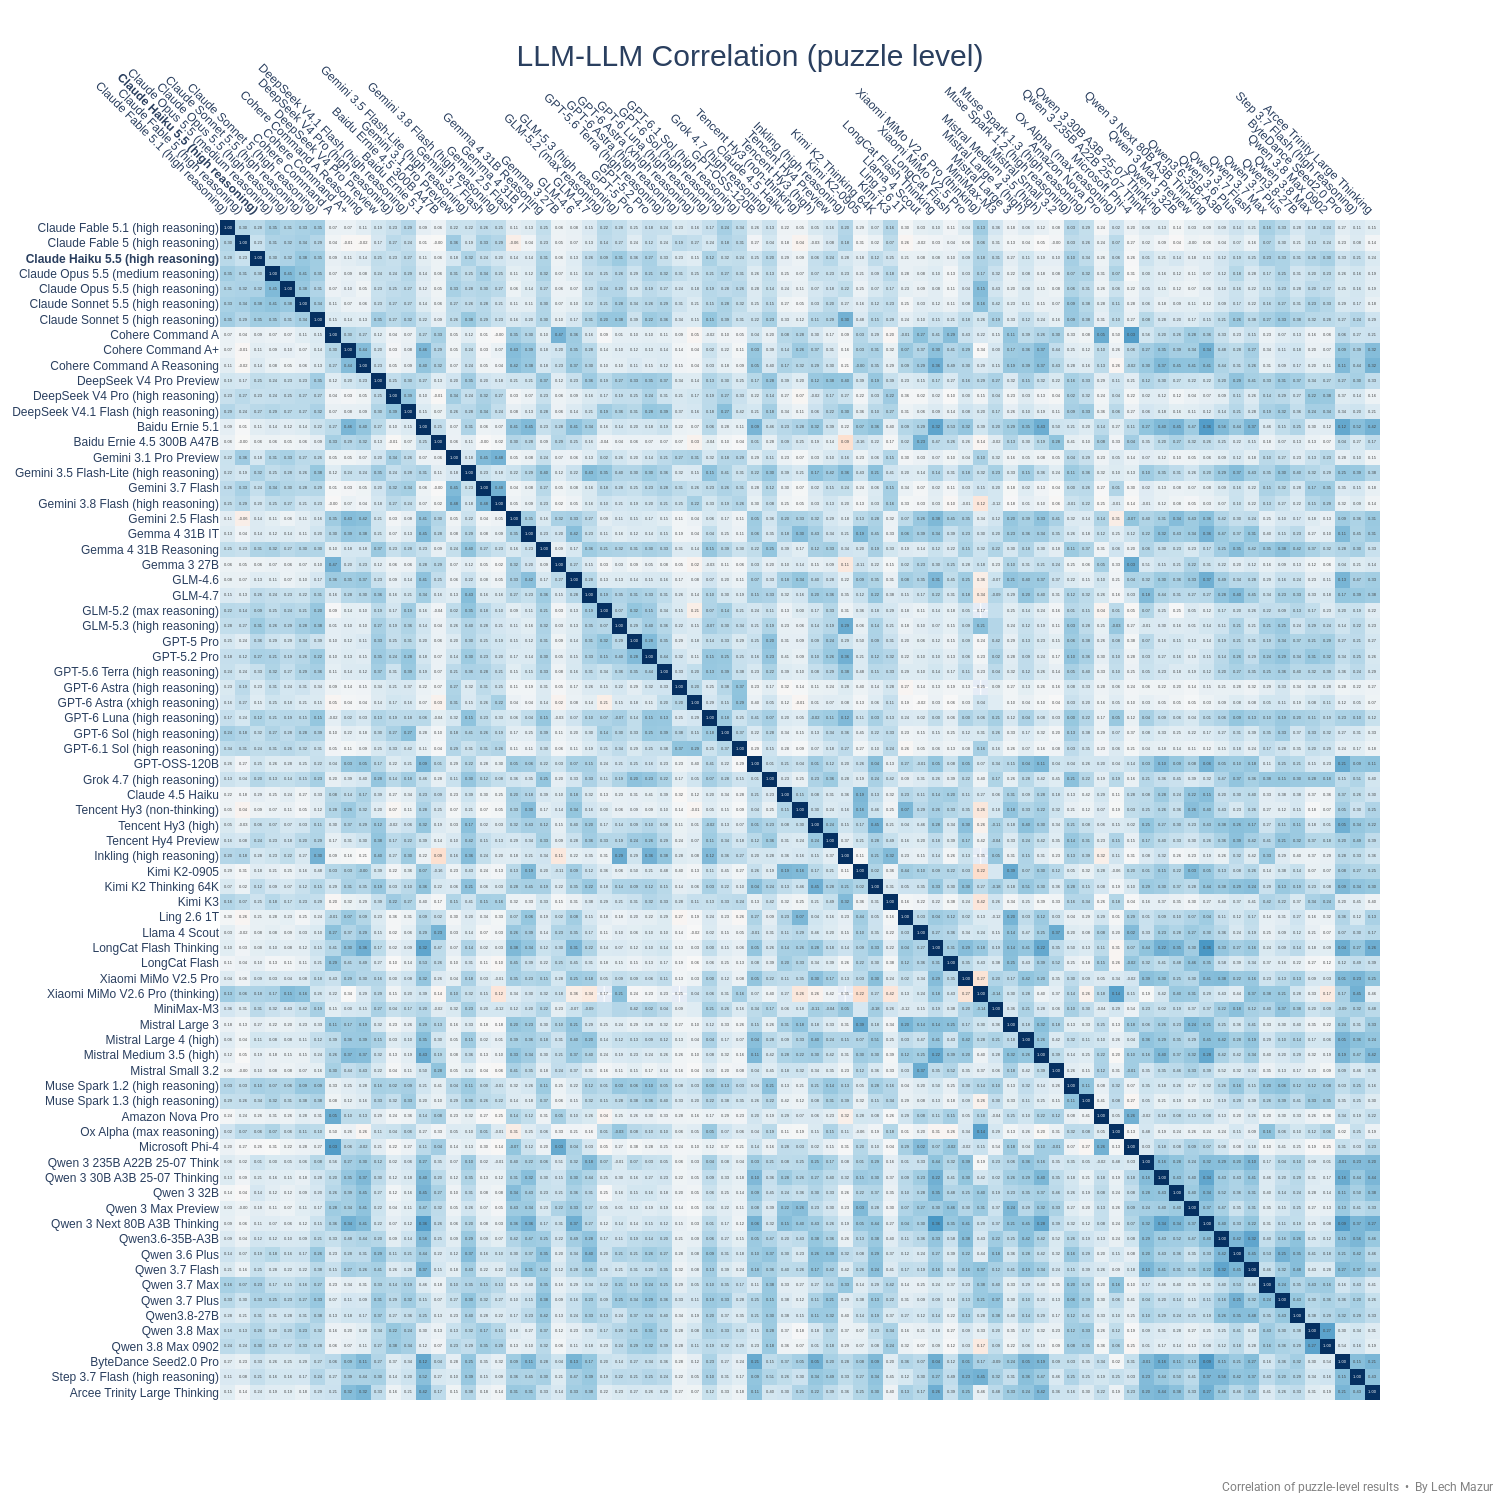
Correlations
CorrelationsOpen full size ↗

Notes

  • Refused or blocked puzzles are scored as 0/4.
  • GLM-5.1 is the provider-default thinking run; GLM-5.2 entries with parenthetical reasoning labels use the stated reasoning setting.
  • Partial credit follows the scoring rule above, which more heavily rewards complete solves.
  • Only one attempt is allowed per puzzle. Humans solving puzzles on the NYT website get four attempts and a notification when they're one step away from the solution.
  • This benchmark is not affiliated with the New York Times

Sources and downloads.

Results as of 2026-10-08. View the original publication ↗